🛰️ Daily AI Frontier
37 works · 2 categories · 14 topics · blog 12 journal 10 arxiv 15 generated 2026-09-03 14:34:15 UTC
Top highlights — Research

LLM Agents 3

Representative image for Repo-To-Skill: Distilling GitHub Repositories Into AI4AI Skills

Repo-To-Skill: Distilling GitHub Repositories Into AI4AI Skills

Rank 88 · Content 95 · Popularity 71

TL;DR - Repo-To-Skill introduces DisCo, an autonomous ML research agent that distills operational knowledge from repositories into compact, verified skills. Adding these skills substantially improves research-agent performance without changing the model backbone, harness, or execution budget.

  • DisCo supports task-agnostic distillation of widely used repositories and task-oriented skill creation for specific research problems.
  • The resulting AREX-Skill Library contains over 5,000 verified skills from 1,000 ML repositories, spanning 20 areas and 178 capability families.
  • With GPT-5.5 and other experimental conditions fixed, skills improved scores by 134.3% on MLE-bench and 34.4% on PaperBench.
  • The same setup also produced gains of 9.2% on FrontierCS and 14.0% on PassNet, indicating that reusable operating context can reduce repeated implementation work.
Representative image for EarlyEval: Cheaper Agent Evaluation via Early Outcome Prediction

EarlyEval: Cheaper Agent Evaluation via Early Outcome Prediction

Rank 87 · Content 95 · Popularity 67

TL;DR - EarlyEval reduces LLM-agent evaluation costs by predicting success or failure from intermediate behavior and stopping runs early. Across three agent benchmarks, it substantially cuts steps and token usage while largely preserving measured resolve rates.

  • Uses paired LightGBM classifiers trained on behavioral, textual, and reference-solution features.
  • Stops execution when either the success or failure classifier crosses a calibrated confidence threshold.
  • Eliminates 13%–26% of agent steps, up to 44.1% of input tokens, and up to 29.4% of output tokens.
  • Achieves 89%–97% prediction accuracy, with average per-agent resolve rates changing by only one to two percentage points.

Coverage, Not Targeting: A Structural Regime in Multi-Turn Agent Credit Assignment

Rank 81 · Content 100 · Popularity 37

TL;DR - This paper argues that when verifiers reveal little about which steps in a multi-turn agent trajectory were correct, broad reward coverage matters more than targeting selected turns. Uniform credit redistribution consistently outperformed concentrated schemes across several agent benchmarks and model families.

  • Defines verifier information density, (V_d=k/C), as the fraction of a causal chain whose per-turn correctness is exposed by the verifier.
  • Terminal-state verification produced low information density—about 0.15 on (\tau^2)-bench and 0.4 on BFCL V3—while the estimated targeting crossover was roughly 0.8.
  • Uniform dense rewards beat sparse outcomes and targeted or randomly concentrated alternatives; shuffled controls were also consistently harmful.
  • A breadth sweep showed a monotonic improvement as more of the causal chain received credit, with the deficit disappearing only at full coverage.

Medical/Healthcare AI 4

Representative image for Seeing Beyond the Lesion: Disease Recognition from Reactive CNS Tissue

Seeing Beyond the Lesion: Disease Recognition from Reactive CNS Tissue

Rank 81 · Content 100 · Popularity 37

TL;DR - Weakly supervised pathology models can predict underlying CNS diseases from reactive, non-lesional biopsy tissue after controlling for sampling-related shortcuts. The findings suggest conventionally non-diagnostic tissue contains subtle disease signals and highlight provenance-only baselines as essential controls.

  • Four pathology foundation models were evaluated as frozen patch encoders on 245 whole-slide images from 186 patients.
  • Coarse disease categories were largely predictable from slide size, exposing a major acquisition confound.
  • For three finer diagnostic distinctions, predictions remained above chance after removing this confound (permutation testing, p ≤ 10⁻⁴).
  • Performance did not significantly differ among the four encoders; contribution maps and expert review assessed whether signals arose from reactive tissue rather than artifacts such as blood.

Late-life semaglutide treatment slows ageing and extends lifespan in female mice

Rank 81 · Content 85 · Popularity 70

TL;DR - A Nature study reports that three months of late-life semaglutide treatment improved physiological function, reduced ageing-associated hallmarks, and extended lifespan in female mice. The findings suggest potential geroprotective effects, but evidence provided is limited to a preclinical female-mouse study.

  • Treatment was administered late in life for three months.
  • Semaglutide attenuated multiple hallmarks of ageing.
  • The intervention modulated nutrient-sensing pathways and conserved genetic regulators of ageing.
  • Whether these effects generalize to male mice or humans is not established by the provided content.
Representative image for Untangling the Mechanisms of Misleading Context in Medical Question Answering

Untangling the Mechanisms of Misleading Context in Medical Question Answering

Rank 78 · Content 95 · Popularity 37

TL;DR - This study examines how fabricated evidence and unsupported assertions corrupt medical reasoning models. Models were especially vulnerable to bare assertions, while access to open reasoning traces substantially improved detection of corrupted decisions.

  • Across three reasoning models, asserted answers were adopted 10–27 percentage points more often than answers suggested by fabricated evidence.
  • Misleading cues appeared in 81–98% of reasoning traces but only 7–90% of final responses, with assertions disclosed less often than evidence-based cues.
  • Fabricated evidence influenced reasoning early and accumulated, whereas bare assertions tended to redirect the conclusion near the end.
  • With guidance, an LLM monitor detected 78% of corrupted decisions at a 5% false-positive rate from an open model’s trace, versus at most 32% from final responses.

Learning to Fuse LLMs with Ontology Rankers for Rare-Disease Diagnosis

Rank 78 · Content 95 · Popularity 37

TL;DR - A learned fusion model combines LLM-generated differential diagnoses with an ontology ranker, improving rare-disease diagnosis while preserving inspectable phenotype-based evidence. It also addresses a documented test-set leakage pathway before evaluation.

  • Fusion improved Phenomizer Recall@1 by 7.86 percentage points on Phenopacket Store and 20.18 points on RAMEDIS.
  • With DeepSeek-V4-Flash, a fusion model trained on other LLMs raised Recall@1 from 0.1657 to 0.2176 without retraining.
  • The model dynamically weighs ranked-list agreement and ontology support for each case.
  • Candidate-level ontology evidence remained available for 90.8% of correct fused diagnoses.

Bioinformatics AI 4

Creating bottom-up RNA transfer vehicles from synthetic protein assemblies

Rank 84 · Content 100 · Popularity 47

TL;DR - Researchers used artificial intelligence to design synthetic virus-like protein assemblies that deliver RNA into cells more effectively than naturally occurring counterparts. The work suggests bottom-up protein design can bypass evolutionary constraints that limit viral delivery systems.

  • Introduces synthetic protein architectures engineered as RNA transfer vehicles.
  • AI-designed assemblies showed superior cellular RNA delivery relative to natural analogues.
  • The bottom-up approach explores designs unavailable through natural viral evolution.
  • The findings could inform more effective RNA delivery platforms.

NucleicBERT interprets RNA sequence space through self-supervised language modelling

Rank 80 · Content 95 · Popularity 47

TL;DR - NucleicBERT is a self-supervised language model trained on large-scale RNA sequence data to learn biologically meaningful patterns without relying on extensive annotations. It could help researchers interpret RNA structure and function from abundant but sparsely annotated sequences.

  • Addresses the scarcity of RNA annotations by learning directly from sequence correlations.
  • Uses self-supervised language modelling across large-scale RNA data.
  • Extracts biologically meaningful patterns from RNA sequence space.
  • Aims to improve inference of RNA structure and function.

3D epigenome of glial cell types in developing human cortex

Rank 80 · Content 95 · Popularity 47

TL;DR - This Nature study maps the 3D epigenomic organization of four glial cell types in the developing human cortex. It connects cell-type-specific gene regulation and chromatin interactions to neuropsychiatric disease variants and human cortical evolution.

  • Profiles glial cells from the mid-gestation human cortex using integrative 3D epigenomic methods.
  • Identifies regulatory elements and chromatin interactions specific to individual glial cell types.
  • Provides a framework for interpreting the potential roles of non-coding neuropsychiatric disease variants.
  • Highlights regulatory features relevant to human-specific cortical evolution.

Towards high-quality large-scale T cell receptor antigen specificity data: challenges and promises

Rank 77 · Content 90 · Popularity 47

TL;DR - This Nature Methods perspective argues that T cell receptor–antigen specificity research is constrained more by noisy, weakly validated data than by data volume. Better experimental validation, statistical filtering, and multimodal AI could enable reliable large-scale datasets for immunology and therapeutic research.

  • High-throughput methods and databases have rapidly expanded available TCR–antigen specificity records.
  • Many existing records lack strong validation or contain substantial noise, limiting their utility.
  • Rigorous experiments and statistical quality controls are needed to produce high-confidence specificity labels.
  • Multimodal AI may help integrate complementary evidence and improve TCR specificity data quality.

LLMs & Foundation Models 5

Evidence for Shared Routing Geometry and Dynamics in Sparse Mixture-of-Experts

Rank 88 · Content 100 · Popularity 61

TL;DR - This paper finds that sparse mixture-of-experts routers across layers share a common geometry and reusable state-transition dynamics once their layer-specific coordinate systems are aligned. The result could enable more accurate prediction or reuse of routing decisions across model depth.

  • Generalized orthogonal Procrustes analysis aligns each router’s control subspace into a shared canonical representation.
  • A single linear transition achieves (R^2=0.39)–(0.71), retaining 79–90% of the predictive power of separate layer-specific dynamics.
  • Router-control states preserve expert choices more faithfully than matched-rank residual representations, distinguishing routing-specific information from generic cross-layer predictability.
  • Learned state evolution improves over simple persistence, reducing (\Delta\mathrm{NLL}) by 15.7% on OLMoE and 6.2% across a 10-router horizon on Phi.

Post-Training Language Models for Gold-Medal Performance in Coding Competitions

Rank 85 · Content 95 · Popularity 62

TL;DR - Researchers developed a post-training and test-time refinement pipeline that enabled Nemotron models to achieve gold-medal-level competitive programming performance. Their specialized Ultra-CC system scored 535.4/600 on IOI 2026, surpassing both the gold threshold and the top human score under equivalent competition constraints.

  • The pipeline combines 22,000 curated problems, synthetic reasoning traces, supervised fine-tuning, and reinforcement learning.
  • GenCorrect iteratively generates, evaluates, and refines diverse candidate solutions using additional test-time compute.
  • On IOI 2025, Nano-CC rose from 130 to 291 points after post-training and reached 468 with GenCorrect; Ultra-CC scored 502.
  • On IOI 2026, the competition-specific Ultra-CC system exceeded the top human score of 498.27 while observing the same time, internet-access, and submission constraints.

Trace as State: Reasoning Traces as Conditional States for Long-Context Transformers

Rank 81 · Content 100 · Popularity 37

TL;DR - Trace as State improves long-context reasoning by placing a previously generated reasoning trace before the original context on a fresh pass, so discovered task state can guide rereading. It substantially outperformed appending the same trace after the context.

  • The paper formalizes conditional state-update tasks and shows that causal processors may require exponentially more memory when task conditions arrive last rather than first.
  • Reasoning traces serve as textual proxies for task state without changing the causal Transformer architecture.
  • Trace as State beat the matched Trace Append control in 26 of 27 model-task-metric combinations across three models and three datasets.
  • On GraphWalks Parents, it raised exact match to 81.8% for DeepSeek V4 Pro Preview and 100.0% for GLM-5.2, versus initial-pass scores of 29.2% and 66.4%, respectively.
Representative image for When Decodability Is Not Enough: Logical Validity Representations, Behavioral Dissociation, and Causal Tests in Language Models

When Decodability Is Not Enough: Logical Validity Representations, Behavioral Dissociation, and Causal Tests in Language Models

Rank 81 · Content 100 · Popularity 37

TL;DR - Hidden states in five open-weight transformers often made logical validity highly decodable even when model answers were near chance. Weak causal effects from probe-derived interventions show that encoding validity, expressing it in outputs, and causally using it are distinct capabilities.

  • Validity remained strongly decodable across held-out templates, semantic domains, and inference families.
  • Validity information was also highly decodable in behaviorally incorrect examples where correctness-conditioned evaluation was applicable.
  • Exhaustive leave-one-out tests identified limits to how broadly these representations generalized.
  • Intervening along learned validity directions produced only weak, nonspecific effects relative to random controls.

LoRA-TSD: Tangent-Space Spectral Descent for LoRA via Muon-Style Updates

Rank 78 · Content 95 · Popularity 37

TL;DR - LoRA-TSD is a geometry-aware optimizer that applies Muon-style spectral descent within the tangent space of the fixed-rank LoRA update. It improves benchmark performance across several model scales while reducing retraction cost and providing convergence guarantees.

  • Treats each LoRA update as a tangent vector on a fixed-rank matrix manifold rather than optimizing its two factors independently.
  • Uses a LoRA-native retraction that is up to 2.8× cheaper than the truncated-SVD retraction used in prior manifold methods.
  • Establishes the tangent-projected gradient as a stationarity measure and gives the first global convergence guarantees under this measure for LoRA-TSD and LoRA-Pro.
  • Outperforms competing LoRA optimizers across six commonsense and natural-language-inference benchmarks using Llama and Qwen models, while remaining robust to adapter rank.

Multimodal & Generative 2

Representative image for SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models

SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models

Rank 91 · Content 100 · Popularity 70

TL;DR - SolarWM is an open foundation for training interactive, long-horizon video world models across heterogeneous datasets and model backbones. It matters because it standardizes data, adaptation, training, and inference while releasing the full pipeline, weights, and recipes for reproducible research.

  • Unifies 1.43 million clips from 10 datasets under a frame-aligned schema containing observations, camera geometry, captions, quality metadata, selection records, and provenance.
  • Adapts four models ranging from 5B to 33B parameters, based on Wan2.2, LTX-2.5, and MiniMax-H3, while retaining each backbone’s native representations and objectives.
  • Uses a three-stage recipe: bidirectional adaptation, teacher-forced autoregressive initialization, and distribution-matching distillation.
  • Produces causal models supporting real-time, minutes-to-hours interactive rollouts despite training on sequences only five seconds long.
Representative image for 打破黑盒猜想:大模型通往真正「空间智能」的破局之路

打破黑盒猜想:大模型通往真正「空间智能」的破局之路

Rank 75 · Content 85 · Popularity N/A

TL;DR - SpatialSV trains multimodal large language models to internalize explicit 3D geometry, improving spatial reasoning without adding inference-time overhead. Its interpretable depth and point-cloud reconstructions also reveal whether failures stem from missing objects, lost spatial anchors, or poor viewpoint alignment.

  • SpatialSV lifts intermediate MLLM features into depth maps, camera-ray maps, and point clouds, supervised with explicit geometric losses during training.
  • The auxiliary 2D-to-3D projection and prediction modules are removed for inference, leaving no additional latency or memory cost.
  • Across eight MLLMs, lower 3D reconstruction error strongly correlates with higher spatial-question-answering accuracy, enabling visual diagnosis of internal representation failures.
  • With only 50% of text annotations, automatically generated 3D supervision raised Qwen2.5-VL-3B accuracy from 47.2% to 53.9%, approaching the 55.3% full-annotation result.

Efficiency & Systems 3

Representative image for Graph Machine: Towards Better Pretraining via Edges

Graph Machine: Towards Better Pretraining via Edges

Rank 88 · Content 100 · Popularity 60

TL;DR - Graph Machine is a sparse architecture that maintains an O(n)-sized state while dynamically retrieving only a few entries through differentiably updated, pointer-like edges. Replacing most dense layers in a 0.6B-parameter Transformer preserved—and in one setting marginally improved—pretraining loss despite extremely sparse retrieval.

  • GM combines O(n) sparse-layer complexity with access to a state whose size can grow with sequence length.
  • Its dynamic routing uses edges updated through a differentiable referral mechanism resembling pointer chasing.
  • The authors replaced 75% of Qwen3-0.6B’s dense Transformer layers and pretrained the model from scratch on 15.7B tokens.
  • Retrieving 2 of 4,096 tokens per KV head caused only slight loss degradation; retrieving 4 yielded the best model and marginally improved loss.

Language Models Can Control Their Own Attention

Rank 87 · Content 95 · Popularity 68

TL;DR - Declarative Attention lets language models explicitly indicate which context regions they need during generation, allowing the inference engine to avoid reading most of the KV cache. On long-context tasks, it substantially reduced attended tokens with modest accuracy losses.

  • The protocol uses three model-declared modes: <global> for full context, <focus> for a specific region, and <local> for recent output only.
  • Unlike proxy-based token selection, the model specifies relevant context intrinsically through chain-of-thought declarations parsed like tool calls.
  • Across 15 zero-shot long-context tasks, attended tokens fell by 52.0% for Gemma-4-31B and 31.1% for Qwen-3.6-27B.
  • Accuracy declined by 1.27 and 2.75 percentage points, respectively, with losses reported to shrink as model scale increases.
Representative image for UE5M3 FP4 Block Scaling for Stable Language Model Pretraining

UE5M3 FP4 Block Scaling for Stable Language Model Pretraining

Rank 81 · Content 100 · Popularity 37

TL;DR - This paper presents an FP4 language-model pretraining recipe that pairs E2M1 values with wide-range UE5M3 block scales, simplifying quantization while improving reported loss and benchmark aggregates. It demonstrates the approach on an 8B Nemotron-H model trained for nearly 190 billion tokens.

  • UE5M3 block scales enable periodic tensor scaling without randomized Hadamard transforms.
  • The recipe selectively applies stochastic rounding to backward gradients and uses FP4 for all eligible internal linear layers.
  • A block-16 configuration achieved lower final-window training loss and quantized-inference validation loss than NVIDIA Transformer Engine’s NVFP4 recipe.
  • Removing RHT and the BF16 final-block exemption increased measured model-body token throughput by 21.2% in a native NVFP4 execution ablation.

AI for Physics 1

Designing physics experiments with artificial intelligence

Rank 87 · Content 95 · Popularity 67

TL;DR - This Nature article explores using AI to design physics experiments by searching vast spaces of hardware configurations and proposing novel experimental layouts. The approach could expand experimental design beyond conventional optimization of a small set of parameters.

  • Frames experimental design as a large-scale search over possible hardware configurations.
  • Emphasizes generating entirely new layouts rather than merely tuning existing setups.
  • Suggests AI can help physicists explore designs that are difficult to identify manually.
  • The provided content does not specify methods, benchmarks, or experimental results.

Embodied AI 2

Representative image for 机械臂做到第10步就容易出错?一个 2B 模型靠动态调整注意力解决了 | IJCAI 2026

机械臂做到第10步就容易出错?一个 2B 模型靠动态调整注意力解决了 | IJCAI 2026

Rank 73 · Content 85 · Popularity 46

TL;DR - S²-VLA is a 2B-parameter vision-language-action model that uses a learned belief state and dynamic attention gating to reduce cumulative errors in long-horizon robotic manipulation. It reports 96.4% success on LIBERO-Long while using about 7GB of inference memory, outperforming many 7B–8.5B models.

  • A lightweight recurrent network derives a belief state from action history and joint-sensor feedback, learning task progress and execution quality without explicit stage labels.
  • Its SSGAA module dynamically balances local visual attention, global intent attention, and action self-attention according to the current manipulation stage.
  • Visual weighting rises for precise alignment, intent weighting rises during grasping and subtask transitions, and action self-attention dominates steady movement.
  • The model reportedly runs at 80.8Hz, highlighting stage-adaptive computation as an efficient alternative to simply scaling VLA parameter counts.
Representative image for 把 Gemini 和 GPT 放到《我的世界》当教练,谁能看懂机器人的微操?

把 Gemini 和 GPT 放到《我的世界》当教练,谁能看懂机器人的微操?

Rank 68 · Content 85 · Popularity 30

TL;DR - Tsinghua University and NVIDIA’s VLM-AR3L framework uses vision-language models to generate absolute and relative reward labels for embodied reinforcement learning, then distills them into a lightweight local network. This produces denser, more stable feedback while reducing VLM queries by roughly 20×.

  • Gemini-2.0-Flash exceeded 70% progress-judgment accuracy across all 10 simulated tasks; GPT-4.1-nano generally reached 60–66%, while some small open models excelled on specific tasks.
  • VLM-AR3L combines absolute goal proximity with pairwise temporal progress, addressing reward drift and cyclic tasks where fixed absolute state rankings fail.
  • Offline VLM labeling trains a compact Siamese reward network, avoiding expensive, latency-heavy API calls during policy optimization.
  • The method achieved 85% success on Minecraft’s Combat Spider and 95% on Milk Cow, and learned several long-horizon tasks where sparse human-authored rewards yielded 0% success.

Explainable AI 1

Explainable deep learning improves human mental models of self-driving cars

Rank 80 · Content 85 · Popularity 67

TL;DR - A Nature paper presents Concept-Wrapper Network, a concept-based explanation method deployed on a real autonomous vehicle. The approach improved drivers’ ability to understand and predict the vehicle’s behavior, suggesting explainability can build more accurate human mental models of autonomous systems.

  • Uses concept-based explanations to communicate autonomous-driving behavior.
  • Evaluated through deployment on a real vehicle rather than only in simulation.
  • Focuses on human understanding and prediction of system behavior.
  • The provided summary does not specify the model architecture, experimental design, or effect sizes.

Immunology 1

Functional chimeric mRNAs encode proteins in mammalian immunity

Rank 73 · Content 85 · Popularity 47

TL;DR - A Nature study reports that inflammation promotes interchromosomal interactions between parent genes, enabling chimeric mRNAs that produce functional proteins involved in mammalian immunity. This suggests gene fusions can be physiologically relevant products of immune responses rather than solely aberrant events.

  • Inflammation brings genes on different chromosomes into close physical proximity.
  • These interactions facilitate the formation of chimeric mRNAs from distinct parent genes.
  • The resulting transcripts encode functional proteins with roles in mammalian immunity.
  • The provided summary does not specify the proteins, mechanisms of RNA fusion, or experimental models.

Quantum Machine Learning 1

Quantum neural operators with implicit quadratic frame and expressivity advantages

Rank 69 · Content 80 · Popularity 45

TL;DR - Wang et al. introduce a hardware-efficient quantum neural operator that uses an implicit quadratic frame to exceed classical linear capacity limits. The approach aims to improve expressivity when solving differential equations on noisy intermediate-scale quantum hardware.

  • The operator implicitly represents quadratic features rather than relying on a classically limited linear formulation.
  • Its design prioritizes hardware efficiency for near-term quantum devices.
  • The claimed advantage is accelerated expressivity for differential-equation solving.
  • The work targets the noisy intermediate-scale quantum era rather than fault-tolerant quantum computing.

Synthetic Biology 1

Rewiring the ribosome to translate proteins encoded in its own RNA

Rank 73 · Content 85 · Popularity 47

TL;DR - A Nature study reports that bacterial ribosomes can be rewired to synthesize proteins encoded within their own ribosomal RNA. This could enable more self-contained translation systems, although the provided abstract does not describe the method or performance.

  • The work links a ribosome’s protein-coding template directly to its own RNA.
  • The demonstrated system uses bacterial ribosomes.
  • The result suggests new ways to engineer ribosomes and redesign biological translation machinery.
  • Quantitative results, limitations, and specific applications are not included in the provided content.
Top highlights — Industry & News

LLM Agents 2

Representative image for 拆解 Claude 5.1:38 小时不睡觉的背后,Anthropic 正在终结「模型论」

拆解 Claude 5.1:38 小时不睡觉的背后,Anthropic 正在终结「模型论」

Rank 75 · Content 85 · Popularity N/A

TL;DR - Anthropic’s reported Claude 5.1 update reframes long-running agents as runtime systems rather than standalone models, emphasizing state consistency, verification, permissions, and asynchronous scheduling. Fable 5.1 and Mythos 5.1 reportedly share an underlying model but expose different capability profiles for general versus restricted professional tasks.

  • A 38-hour unattended workflow illustrates dynamic replanning, parallel experiments, and recovery from invalid data rather than rigid execution of an initial plan.
  • Reliable long-horizon agents require external sources of truth, dependency-aware invalidation, tool-based verification, and checkpoints containing validated state.
  • Capability routing continually adjusts tool and resource permissions according to identity, task state, and execution history.
  • Scientific agents increasingly orchestrate asynchronous, provenance-tracked DAGs of specialist tools, shifting evaluation and cost measurement from individual inferences to complete task episodes.
Representative image for WorkBuddy金融版正式发布,让Agent真正进入金融业务现场

WorkBuddy金融版正式发布,让Agent真正进入金融业务现场

Rank 64 · Content 70 · Popularity N/A

TL;DR - Tencent launched WorkBuddy Financial Edition, an AI agent workspace for banks, brokerages, asset managers, and insurers. It combines specialized agents, financial data connectors, workflow automation, and tiered security controls to deploy agents in regulated business processes.

  • Provides 80+ financial experts and expert teams across corporate banking, retail finance, investment research, advisory, and customer management.
  • Integrates market, corporate-registration, fund-rating, analyst-consensus, and research data, with traceable outputs and cross-source verification.
  • Supports private deployment, dedicated VPC, and SaaS configurations, plus granular permissions, data masking, encryption, audit logs, and human approval through WeCom.
  • Tencent reports shortening corporate credit due diligence from about 10 days to one day and reducing several research and insurance workflows by roughly 10×.

Medical/Healthcare AI 1

Healthcare organizations can now connect EHR and additional industry data to ChatGPT

Rank 71 · Content 80 · Popularity N/A

TL;DR - OpenAI says healthcare organizations can now connect electronic health records and other trusted industry data to ChatGPT. The integration aims to give clinicians secure access to relevant patient context and medical research.

  • Supports connections to EHRs and additional healthcare data sources.
  • Designed to surface patient context within ChatGPT-assisted workflows.
  • Also provides access to medical research and related information.
  • Technical architecture, security controls, and measured outcomes are not detailed in the provided content.

LLMs & Foundation Models 1

Introducing Gemini 3.8 Flash and 3.8 Flash Cyber

Rank 68 · Content 75 · Popularity N/A

TL;DR - Google DeepMind announced Gemini 3.8 Flash and a cybersecurity-focused variant, Gemini 3.8 Flash Cyber. Because no article content was provided, specific capabilities, benchmarks, availability, and technical improvements cannot be verified.

  • Gemini 3.8 Flash appears to extend Google’s Flash model line.
  • Gemini 3.8 Flash Cyber is presented as a specialized cybersecurity model or variant.
  • The supplied title alone does not establish architecture details, performance results, pricing, or release scope.

Multimodal & Generative 2

NeoMME: an efficient Multimodal-native and Multilingual Encoder

Rank 71 · Content 80 · Popularity N/A

TL;DR - Hugging Face introduces NeoMME as an efficiency-focused, multimodal-native, multilingual encoder. Because only the title is provided, its architecture, supported modalities, benchmarks, and availability cannot be assessed.

  • Designed as an encoder rather than a general-purpose generative model.
  • Targets both multimodal and multilingual inputs.
  • Emphasizes efficiency, though no measurements or comparisons are provided.
  • The available metadata contains no technical details or reported results.
Representative image for 世界生成模型来了3D头部玩家,可进入生产管线的场景级生成时代来临!

世界生成模型来了3D头部玩家,可进入生产管线的场景级生成时代来临!

Rank 68 · Content 75 · Popularity N/A

TL;DR - Hyper3D launched WorldGen, a scene-level 3D generation system that turns a single image into an editable, interactive environment in roughly 2–3 minutes. Its production-oriented output could accelerate workflows in robotics simulation, games, film, XR, and spatial design.

  • WorldGen decomposes scenes into independent 3D assets while preserving spatial relationships, rather than producing a single inseparable model.
  • Its SimReady mode adds collision geometry and estimates physical properties such as mass, friction, and restitution for simulation use.
  • The system generates foreground objects individually, completes backgrounds with 3D Gaussian Splatting, and exports assets to tools including Blender, Unity, Unreal Engine, and Isaac Sim.
  • WorldGen builds on CAST, Hyper3D’s SIGGRAPH 2025 best-paper framework for object completion, scene alignment, relationship modeling, and physics-based correction.

Efficiency & Systems 1

Representative image for 视频生成算力新选择:SmarCo GC3如何绕过“存储墙”这道硬门槛

视频生成算力新选择:SmarCo GC3如何绕过“存储墙”这道硬门槛

Rank 68 · Content 75 · Popularity N/A

TL;DR - 中科通量推出面向视频生成的 SmarCo GC3,宣称通过 RISC-V 数据流架构减少片外内存的数据搬运,以缓解传统 GPU 的“存储墙”。其实际性能、工具链成熟度和 AI 框架兼容性仍有待生产环境测试验证。

  • SmarCo GC3 按数据依赖动态触发计算,并让中间特征在片上节点间流转,而非频繁往返显存。
  • 芯片标称提供 200 TOPS(INT8)算力、128GB LPDDR5 ECC 统一内存,以及 128 路 1080P 硬件解码能力。
  • 其设计旨在将扩散模型和时序注意力的数据依赖图直接映射到硬件,以支持多路并行及更长时间的视频生成。
  • RISC-V 向量扩展和定制指令可加速 Transformer 常用算子,但文章未提供实测基准来证明其相对 GPU 的性能或能效优势。

Embodied Robotics 1

Representative image for ZINOVA携手逐际动力,探索机器人在复杂建筑施工中的应用

ZINOVA携手逐际动力,探索机器人在复杂建筑施工中的应用

Rank 64 · Content 70 · Popularity N/A

TL;DR - ZINOVA and LimX Dynamics demonstrated two TRON 2 dual-arm robots performing a scaled tilt-up concrete construction workflow, including formwork assembly and multilayer rebar placement and tying. The proof of concept suggests that modular robots using existing tools could support complex, nonstandard construction tasks.

  • ZINOVA’s “Tool Intelligence” framework combines general-purpose grasping, force/torque/vibration sensing through its TEISI interface, and task-specific robot configurations.
  • Two TRON 2 robots coordinated with tools such as a nail gun and boards to assemble formwork, then placed and tied rebar across multiple layers.
  • TRON 2’s modular hardware, SDK, teleoperation interfaces, and interchangeable tools and bases enable one platform to address multiple construction processes.
  • The current approach keeps humans in the loop at critical steps while collecting real-world interaction data intended to improve future autonomy and model training.

Robotics 1

Representative image for 今年最难的机器人Demo,“机器人含量”为0

今年最难的机器人Demo,“机器人含量”为0

Rank 71 · Content 80 · Popularity N/A

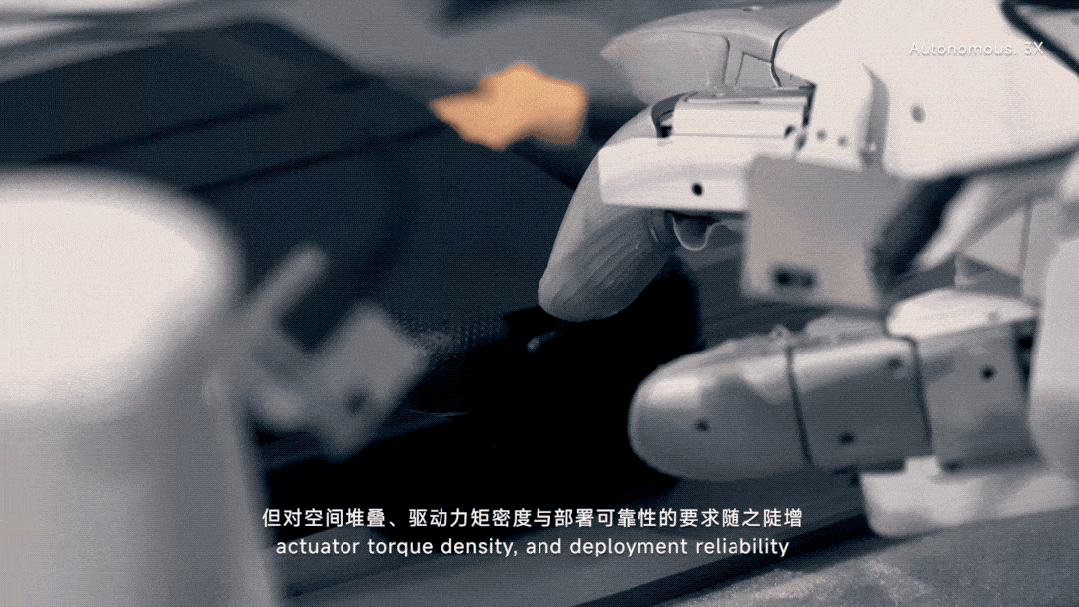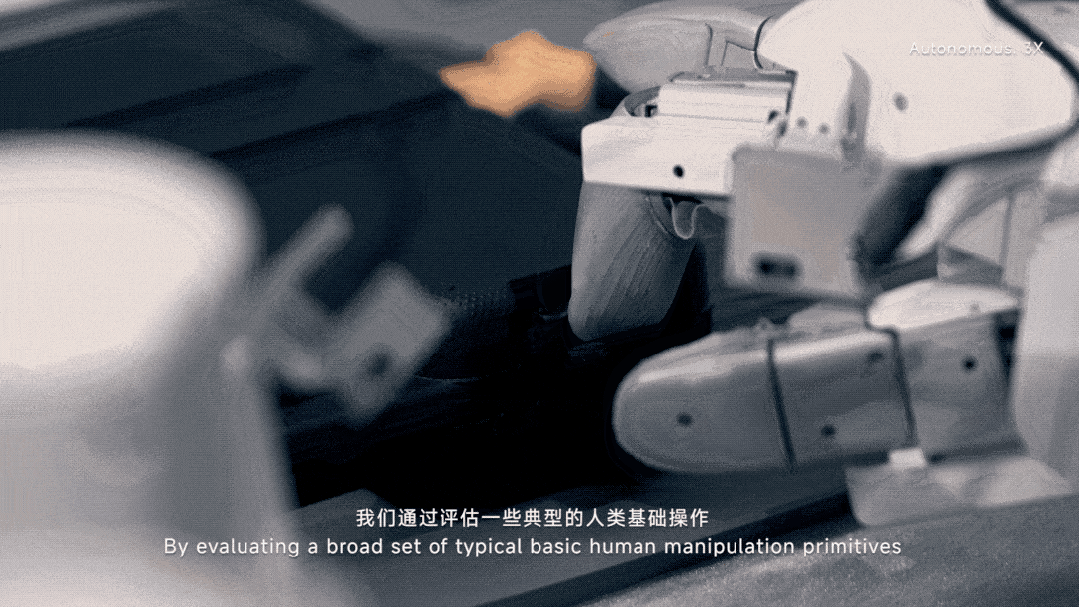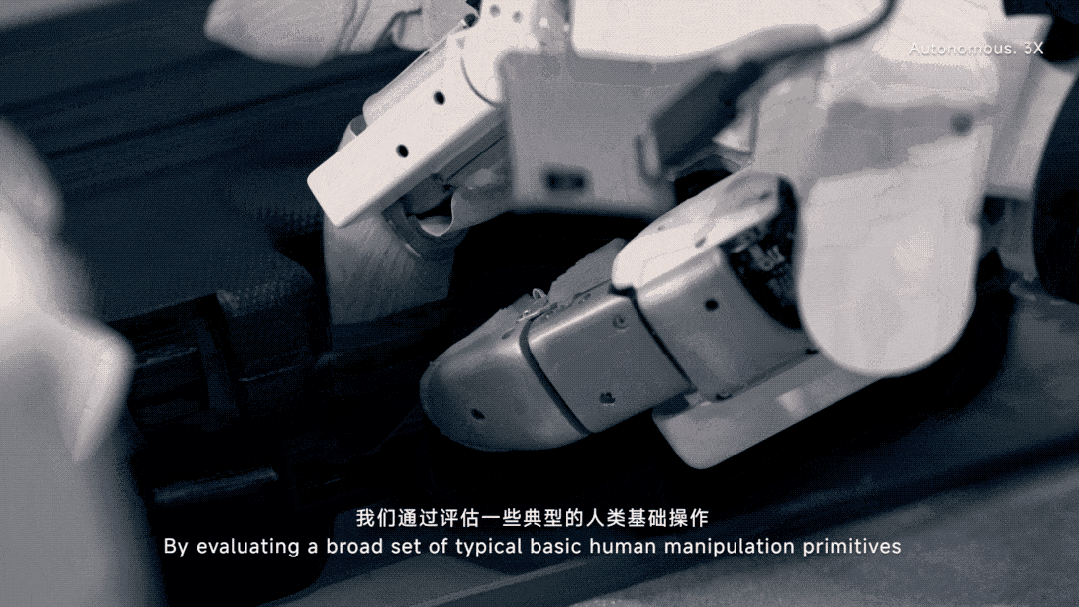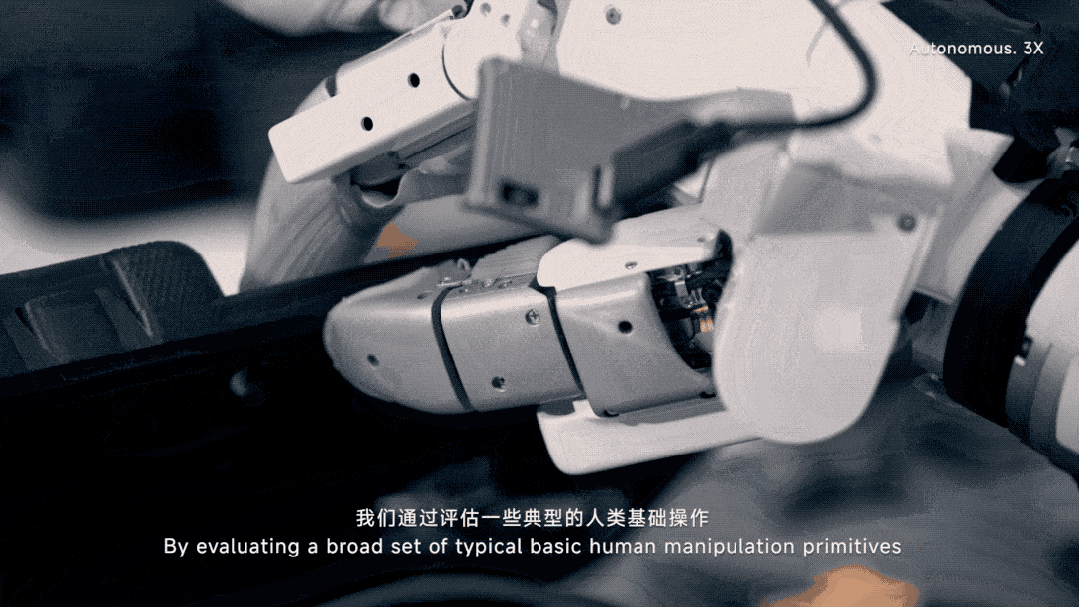
TL;DR - X2 Robot introduced TwinDEX, a three-finger dexterous manipulation system that completed multi-step laboratory tasks without target-robot teleoperation data during post-training. Its matched wearable data collector and robotic end effector could make high-quality embodied-AI data substantially easier to scale.

  • TwinDEX performed a 24-step chemistry workflow involving three tools, bimanual coordination, cap twisting, syringe operation, pouring, and other precision actions.
  • The system uses an isomorphic three-finger, nine-degree-of-freedom design for both wearable data collection and robot execution, reducing embodiment-transfer errors.
  • X2 Robot reports that TwinDEX generated usable trajectories 5.3 times faster than conventional robot teleoperation.
  • In the reported tasks, policies trained on a few hundred embodiment-free demonstrations approached the performance and scaling behavior of those trained with robot teleoperation data.