🛰️ Daily AI Frontier
32 works · 3 categories · 13 topics · blog 12 journal 7 arxiv 15 generated 2026-09-16 14:20:57 UTC
Top highlights — Research

LLM Agents 4

Nameless Tokenization: A Lossless Tokenizer-Level Defense Against Control-Token Forgery in Open-Weight LLMs

Rank 82 · Content 100 · Popularity 39

TL;DR - Nameless tokenization removes surface strings from reserved control-token identifiers, preventing prompt content from forging chat, tool, or reasoning boundaries without altering benign inputs. An audit of 256 deployed chat tokenizers found all were forgeable, while the commonly recommended mitigation still left 56.6% vulnerable.

  • The defense ensures ordinary content encoders cannot emit reserved control identifiers while preserving message text unchanged.
  • Across five tokenizer families, it exactly reproduced standard token streams for attack-free data.
  • Accuracy on delimiter-bearing text increased from 8.5% to 59.9%, outperforming sanitization approaches that discard or alter content.
  • Experiments indicate reserved identifiers carry most of the influence in forged tool results and forged turns when system instructions frame user content as data.
Representative image for ScienceBuddy: Recursive-in-Recursive Self-Improvement for Interactive Scientific Agents

ScienceBuddy: Recursive-in-Recursive Self-Improvement for Interactive Scientific Agents

Rank 82 · Content 90 · Popularity 62

TL;DR - ScienceBuddy is an interactive workspace for scientific agents that continually improves by learning from researchers’ requests, feedback, and execution evidence. Its “recursive-in-recursive” approach jointly evolves the agent harness and trains the underlying model.

  • Inner recursion refines the harness while keeping the model fixed.
  • Outer recursion applies reinforcement learning to the model under the improved harness.
  • User interactions and execution traces become training tasks and evaluation rubrics.
  • Case studies span four scientific task families, though the abstract reports no quantitative results.

Agentic Societies Need a Social Harness

Rank 78 · Content 95 · Popularity 39

TL;DR - This paper argues that multi-agent AI systems operating across trust boundaries need a shared “social harness” to govern inter-agent communication. Experiments indicate that current harnesses and messaging primitives can fail even among honest agents and can be exploited by faulty or malicious participants.

  • Agentic societies involve autonomous agents representing principals whose objectives may only partially align.
  • Communication vulnerabilities can let adversarial agents stall collaboration, manipulate outcomes, or pursue harmful goals.
  • The proposed layered architecture aims to prevent some failures, detect invalid messages at runtime, and support post-incident investigation and consequences.
  • The social harness complements each agent’s personal harness, which manages private context and principal communication.
Representative image for Coding Agents Have Converged: Why the SWE-bench Leaderboard Can No Longer Order Its Top Entries, and What to Measure Instead

Coding Agents Have Converged: Why the SWE-bench Leaderboard Can No Longer Order Its Top Entries, and What to Measure Instead

Rank 78 · Content 95 · Popularity 39

TL;DR - An audit of 254 SWE-bench submissions finds that small score gaps cannot reliably rank leading coding agents because their successes overlap heavily and results depend on model-scaffold pairings. The authors propose reporting statistical resolution, grouping sensitivity, and model-scaffold provenance instead of treating aggregate scores as definitive rankings.

  • The top two SWE-bench Verified entries both solve 396 of 500 tasks; none of the 29 adjacent top-30 pairs differ significantly under exact paired McNemar tests at α=0.05.
  • Top-ten systems share 285 successes and 51 failures, with a median solution-set nesting of 0.935 versus a score-implied baseline of 0.774.
  • Within-model scaffold performance ranges reach 29.8 percentage points, exceeding the top-30 score spread of 8.8 points, though the observational analysis does not establish causality.
  • The larger Test split distinguishes 14 of 23 adjacent pairs, indicating that evaluation-set size materially affects leaderboard resolution.

Medical/Healthcare AI 2

Memorisation bias in medical AI

Rank 82 · Content 100 · Popularity 39

TL;DR - This paper identifies “memorisation bias,” where medical AI predictions on a patient’s future records are altered because the model previously saw that patient’s anonymized historical data. The effect can distort clinical accuracy and persist for decades, creating risks when training-data contributors later return for care.

  • Memorisation bias appears across multiple data modalities and model architectures.
  • For new conditions absent from a patient’s historical training records, diagnostic sensitivity decreased.
  • For unchanged health states, both sensitivity and specificity were artificially inflated.
  • Current de-identification practices hinder identifying returning contributors, suggesting training and deployment protocols may need revision.

Will wearable technologies transform clinical trials?

Rank 67 · Content 75 · Popularity 49

TL;DR - Nature examines the growing use of digital wearables in clinical research and the unresolved debate over whether their measurements are rigorous enough to meaningfully transform clinical trials.

  • Wearable technologies are increasingly being incorporated into research settings.
  • Their potential value lies in collecting digital health data during clinical trials.
  • Questions remain about the scientific validity, reliability, and real-world impact of wearable-derived measurements.
  • The provided excerpt does not report specific devices, methods, or study results.

Bioinformatics AI 1

Map of brain ‘microproteins’ could offer new clues to Alzheimer’s disease

Rank 78 · Content 90 · Popularity 49

TL;DR - Researchers mapped more than 1,000 previously overlooked microproteins in human brain tissue. Some differ in Alzheimer’s disease, suggesting new avenues for investigating its molecular mechanisms.

  • The study expands the known catalog of proteins expressed in the human brain.
  • It focuses on microproteins, which can be missed by conventional protein-detection approaches.
  • Alzheimer’s-associated alterations make some microproteins potential targets for further mechanistic and biomarker research.
  • The provided summary does not specify the detection methods or clinical significance.

LLMs & Foundation Models 5

ImpossibleRubrics: Stress-Testing Generated Rubrics as Reward Signals

Rank 88 · Content 100 · Popularity 61

TL;DR - ImpossibleRubrics is a 169-task benchmark testing whether LLM-generated rubrics reward honest acknowledgment of impossible requests over adversarially fabricated answers. It reveals that rubric specificity can worsen reward hacking by signaling which false claims attackers should make.

  • Eleven rubric generators were exploited on 8–26% of tasks in the unbiased evaluation cut.
  • On a deliberately selected stress cut, the strongest tested generator was exploited 36% of the time, versus 0% for a certificate-faithful rubric.
  • Seven of eleven tailored-rubric generators performed worse than a generic “be decisive, penalize hedging” rubric, which had a 64% exploitation rate.
  • Each task includes a verifiable oracle certificate defining permissible claims, enabling systematic detection of certificate-violating answers.

OPEN-1B: A Fully Auditable Training Run

Rank 82 · Content 100 · Popularity 39

TL;DR - OPEN-1B is a 1B-parameter language model whose distributed training trajectory can be independently replayed and verified bit-for-bit across heterogeneous commodity hardware. This enables auditors to check that published checkpoints genuinely came from the disclosed data, code, and training recipe.

  • The method imposes fixed ordering on GPU reductions, data batches, and inter/intra-node collective communication to eliminate major sources of training nondeterminism.
  • Any individual distributed-training step can be replayed on a single commodity device and compared with the published trajectory.
  • A collective verification scheme distributes individual-step audits across many participants, avoiding the infeasible cost of replaying the entire run on one machine.
  • The release includes the full pretraining dataset, all intermediate checkpoints, training code, and an audit harness.

Where Should a Document Live: Context, Representations, or Parameters?

Rank 82 · Content 100 · Popularity 39

TL;DR - This paper compares storing new knowledge in LLM context, KV-cache representations, or fine-tuned parameters. KV-based Cartridges deliver the strongest accuracy and retrieval performance but can cause substantial catastrophic forgetting.

  • In oracle tests across five knowledge-intensive benchmarks, Cartridges outperform parametric methods by roughly 10 points at nearly every storage budget.
  • KV Compaction remains competitive only at low compression, trailing parametric methods by 10 points beyond (50\times) compression.
  • In multi-document retrieval, Cartridges alone match in-context learning, beating parametric methods by 29 points and Compaction by 15 points.
  • Cartridges reduce control-benchmark performance by 6%, including a 13% decline on coding tasks.

Coupled Calibration and Learning: Mitigating Teacher Bias in LLM Distillation without Target-Domain Reward Feedback

Rank 78 · Content 95 · Popularity 39

TL;DR - Coupled Calibration and Learning (CCL) is an LLM distillation method that jointly calibrates a biased teacher and trains a student under target-domain covariate shift, without target-domain reward feedback. The authors theoretically show that CCL can recover the optimal student within its policy class, whereas direct teacher matching may retain persistent error.

  • CCL uses source-domain reward feedback to calibrate the teacher, then trains the student on target questions through token-level branching.
  • Teacher calibration and student learning form an iterative feedback loop, with each updated student informing subsequent calibration.
  • In an autoregressive policy framework, the student’s expected average KL divergence to an oracle student converges to zero at a polynomial rate.
  • Regularized direct matching can remain bounded away from the oracle even when the teacher outperforms every student policy on regularized target reward.
Representative image for Large Language Models Develop Belief State Geometry In-Context

Large Language Models Develop Belief State Geometry In-Context

Rank 78 · Content 95 · Popularity 39

TL;DR - A controlled study finds that LLM activations encode hidden Markov model belief states during in-context learning. Causal interventions suggest this geometry is functionally involved in prediction, supporting the view that LLMs approximate Bayesian inference over context-inferred models.

  • Belief states were linearly decoded from residual-stream activations across six open-source LLMs and 40 non-trivial HMMs.
  • Peak probe performance ranged from (R^2=0.83) to (0.99), appearing at layers ranging from early to late.
  • Patching and steering the identified subspace preserved prediction quality near that of unmodified models, while control interventions substantially degraded it.
  • The results extend activation-geometry findings from HMM-trained toy networks to production-scale LLMs.

Multimodal & Generative 1

Same Flow, Different Paths: Variance Reduction in Flow Matching

Rank 78 · Content 95 · Popularity 39

TL;DR - This paper shows that flow-matching paths inducing the same objective can produce different stochastic-gradient variance and SGD convergence rates. It develops a constrained path-optimization method for reducing variance without changing the underlying flow-matching problem.

  • Derives near-tight SGD iteration-complexity bounds for a linear velocity model with one-dimensional Gaussian data and identifies an optimal linear path.
  • Generalizes path selection as a variance-minimization problem constrained to preserve the marginal distributions and velocity field.
  • Shows that unconstrained variance reduction can paradoxically slow convergence, making flow-preserving constraints essential.
  • Reformulates otherwise intractable constraints into sample-estimable ones and supports the theory on synthetic and real datasets.

Efficiency & Systems 2

JustFit: 200K-Token LLM Serving on a 24 GiB Laptop with Just-in-Time State Management

Rank 83 · Content 100 · Popularity 43

TL;DR - JustFit is an MLX-based runtime that serves Qwen3.8-27B with more than 200K tokens of context on a 24 GiB MacBook by compressing and managing execution state just in time. It expands local long-context inference capacity without depending on additional model-weight quantization.

  • Completed 196,608 input plus 16,384 output tokens in three runs, reaching 212,992 positions—6.93× the mlx-vlm baseline.
  • Combines compressed KV execution, component residency swapping, and state-preserving serving transitions.
  • Achieved 19.11 tokens/s on a 32K-input, 64-output test and a median 16,374 MiB peak footprint on a repeated 32K+6K workload.
  • The integrated runtime correctly answered 29 of 30 AIME 2026 problems.

LoopSpec: Pipelined Self-Speculative Decoding for Looped Transformers

Rank 81 · Content 90 · Popularity 59

TL;DR - LoopSpec is a training-free, self-speculative decoding framework that uses intermediate recurrent states in Looped Transformers to draft tokens while pipelining their generation with verification. It delivers up to 6.83× inference speedup on reasoning and coding benchmarks while preserving exact decoding behavior.

  • Generates draft predictions from early recurrent depths without requiring a separate draft model.
  • Overlaps future-token drafting with current-token verification to reduce decoding latency.
  • Selectively adds a second proposal from a deeper recurrent state to improve draft accuracy with limited compute overhead.
  • Supports lossless greedy and sampling-based decoding, with proposal depths derived in closed form and validated empirically.

Cryo-Electron Microscopy 1

When a laser beam hits an electron beam

Rank 70 · Content 80 · Popularity 48

TL;DR - Specially engineered transmission electron microscope prototypes use laser–electron beam interactions to substantially improve image contrast for cryo-EM and cryo-ET. This could make structural and tomographic imaging more informative, though the provided summary does not report quantitative results.

  • The work focuses on prototype transmission electron microscopes with specialized engineering.
  • Their key advance is greatly improved contrast in cryo-EM and cryo-ET images.
  • Better contrast could aid visualization in structural biology and cellular tomography.
  • No specific performance metrics, biological applications, or deployment details are provided.

Evolutionary Microbiology 1

These bizarre, much-coveted microbes are revealing the origins of complex life

Rank 60 · Content 65 · Popularity 49

TL;DR - Researchers are racing to culture unusual microbes that could illuminate how complex life originated. The provided excerpt says these organisms are yielding surprises but does not specify particular findings.

  • The work focuses on growing exotic, highly sought-after microorganisms in laboratory cultures.
  • Studying these microbes could clarify evolutionary steps leading to complex life.
  • Nature characterizes the research as an active, competitive effort involving a growing variety of organisms.
  • No specific organisms, methods or experimental results are described in the provided content.

Quantum Machine Learning 1

Publisher Correction: Quantum neural operators with implicit quadratic frame and expressivity advantages

Rank 25 · Content 15 · Popularity 49

TL;DR - This is a publisher correction to a Nature Machine Intelligence paper on quantum neural operators using an implicit quadratic frame and claiming expressivity advantages. The provided content does not specify what was corrected or whether the paper’s conclusions changed.

  • Published online on 14 September 2026.
  • The underlying work concerns quantum neural operator architecture and expressivity.
  • No technical results, correction details, or revised claims are included in the provided text.

Safe Policy Learning 1

Conformal Policy Learning with Distribution-Free Safety Guarantees

Rank 78 · Content 95 · Popularity 39

TL;DR - Conformal policy learning uses hypothesis tests of counterfactual harm to decide who receives treatment, providing distribution-free safety guarantees in high-stakes settings. It aims to improve welfare while explicitly limiting the probability of treating individuals who would be worse off than under control.

  • Treatment is assigned by thresholding conformal p-values built from observable proxies and selective calibration.
  • For randomized experiments, CPL offers finite-sample safety at a user-specified level under exchangeability, without outcome-model assumptions.
  • With consistent outcome estimation, CPL is asymptotically welfare-optimal subject to the safety constraint.
  • For observational studies, learn-then-balance weighting yields doubly robust safety guarantees.

Structured Data AI 1

Representative image for LimiX-2: A Contextual Mechanism Network Towards General Structured-Data Intelligence

LimiX-2: A Contextual Mechanism Network Towards General Structured-Data Intelligence 🔗 3 sources

Rank 88 · Content 95 · Popularity 70

TL;DR — LimiX-2 is a 400M-parameter foundation model for structured data that models context-dependent joint data-generating mechanisms rather than only predicting a predefined target. It reportedly leads the TabArena, BCCO, and TALENT benchmarks while unifying prediction, imputation, and causal-structure discovery in one framework.

  • Its Contextual Mechanism Networks learn (p(x, y \mid D_{\mathrm{context}})), representing dependencies among variables through cell-level features and context rather than training solely for target prediction.
  • Pretraining uses Context-Conditional Masked Modeling on synthetic data generated from diverse structural causal models, including linear, nonlinear, interaction or multivariable, periodic, and noisy distributions.
  • Classification, regression, and missing-value imputation are formulated as different queries over the same learned data model.
  • The model achieved reported overall Elo scores of 1935 on TabArena, 1432 on BCCO, and 1506 on TALENT, outperforming dataset-specific methods and existing tabular foundation models overall.
  • Feature attention can capture direct causal relationships, allowing the framework to recover causal graph skeletons in addition to performing predictive tasks.

Note: The paper summary emphasizes joint mechanism modeling and causal-skeleton recovery, while the media sources emphasize the 400M-parameter scale, benchmark rankings, and applicability to enterprise tabular tasks.

Top highlights — Industry & News

LLM Agents 4

Representative image for 豆包 2.1 Pro模型更新,已接入豆包工作

豆包 2.1 Pro模型更新,已接入豆包工作

Rank 78 · Content 90 · Popularity N/A

TL;DR - ByteDance updated Doubao 2.1 Pro to version 0915, improving multimodal coding, long-horizon agent tasks, and tool use while reducing token consumption. The model is now broadly available through Volcano Ark’s API and integrated into Doubao Work.

  • Multimodal understanding improved for video reasoning, 3D object recognition, and image-to-code workflows spanning web design, games, and 3D modeling.
  • In a reported test on 1,000 historical Luanti issues, parallel sub-agents brought 83% of fixes to a merge-ready standard within nearly 36 hours.
  • Long-running research and automation tasks gained stronger source tracing, multilingual retrieval, recency assessment, and cross-source data verification.
  • Image and video reasoning reportedly consume over 30% fewer tokens than the previous version, with fewer reasoning rounds and tool calls.
Representative image for 协同办公进入Agent时代,飞书+豆包工作跑在了最前面

协同办公进入Agent时代,飞书+豆包工作跑在了最前面

Rank 68 · Content 75 · Popularity N/A

TL;DR - ByteDance unveiled Feishu 8.0 and Doubao Work Partner, integrating enterprise agents directly into collaborative workflows. The launch matters because it treats agents as managed organizational participants that can access tools and context, collaborate with people and other agents, and operate under enterprise security controls.

  • Feishu 8.0 lets agents use messaging, documents, multidimensional tables, calendars, approvals, meetings, and project workflows much like human employees.
  • Doubao Work Partner is a team agent with its own organizational identity that can join chats and meetings, read authorized documents and code, coordinate across groups, and proactively follow up on work.
  • Native Feishu integration provides shared accounts, organizational context, inherited permissions, usage auditing, configurable limits, and watermarking and encryption controls.
  • Agents can collaborate through mentions, execute tasks in parallel, consolidate discussions into summaries and action items, and preserve team knowledge beyond individual employees.
Representative image for 高通技术公司携手中兴努比亚和豆包手机助手,共同推动智能手机迈入个人AI新时代

高通技术公司携手中兴努比亚和豆包手机助手,共同推动智能手机迈入个人AI新时代

Rank 64 · Content 70 · Popularity N/A

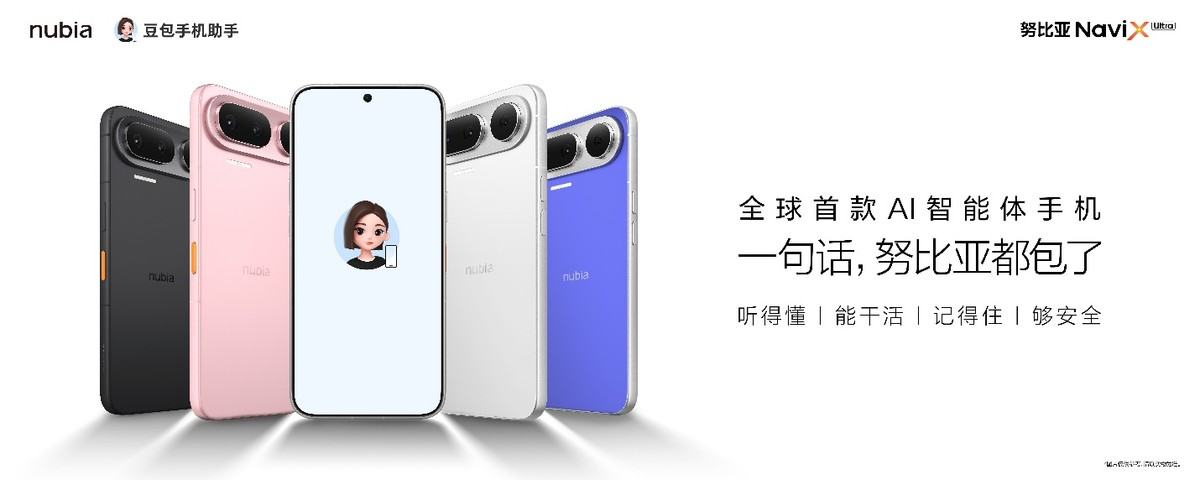
TL;DR - Nubia launched the NaviX Ultra smartphone with Qualcomm’s fifth-generation Snapdragon 8 Elite platform and the Doubao mobile assistant, targeting responsive on-device agentic AI. The collaboration marks an effort to bring personal agents and cross-app task execution to consumer smartphones at scale.

  • The chipset combines a third-generation Qualcomm Oryon CPU, a redesigned Adreno GPU, and a Hexagon NPU optimized for generative and agentic AI workloads.
  • Hardware-software co-optimization is intended to improve performance and energy efficiency for continuous conversations, multitasking, and complex cross-app operations.
  • Users can quickly invoke the assistant through multiple methods, while the system aims to understand preferences and context and proactively help complete tasks.
  • Qualcomm, Nubia, and Doubao position the device as an ecosystem-level integration of mobile hardware, natural-language understanding, and agent capabilities.
Representative image for “阿宝”交新朋友:携手比亚迪“迪迪虾”,实现车机端一句话办事

“阿宝”交新朋友:携手比亚迪“迪迪虾”,实现车机端一句话办事

Rank 64 · Content 70 · Popularity N/A

TL;DR - Alipay’s Abao agent now works with BYD’s “Didixia” in-car AI agent, letting Denza N8L drivers use voice commands to complete services such as parking payments and coffee orders. The integration demonstrates secure, cross-device agent collaboration for real-world transactions.

  • Didixia handles in-car voice interaction and intent recognition, while Abao matches and executes services within Alipay.
  • Payments require voiceprint verification and active user confirmation, with each agent restricted from accessing the other platform’s unrelated private data.
  • The integration uses Alipay’s AHA multi-agent interoperability protocol to coordinate service discovery, execution, and transaction completion.
  • Initial services include parking payments, coffee ordering, coupon collection, and Ant Forest energy collection.

Bioinformatics AI 1

Representative image for 被英伟达点名的杭州团队,补上了AI for Science的「最后一公里」

被英伟达点名的杭州团队,补上了AI for Science的「最后一公里」

Rank 71 · Content 80 · Popularity N/A

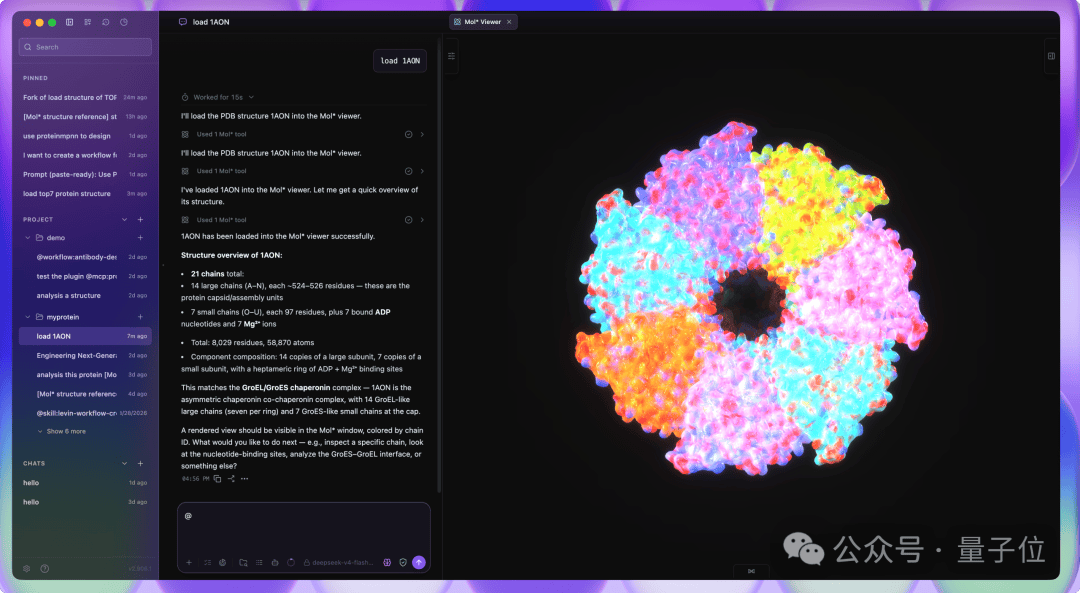
TL;DR - Hangzhou-based protein design company Lévin released Lévin Harness, an agentic workspace that connects scientific models, analysis tools, compute, data, and reusable workflows. It aims to close the AI-for-science loop from research planning and protein design through result analysis and experimental feedback.

  • General-purpose LLMs plan tasks and interpret natural-language requests, while specialized tools handle protein structure prediction, sequence design, and candidate evaluation.
  • A plugin system standardizes model installation, inputs, outputs, and execution, while supporting local workstations and remote GPU servers.
  • Integrated 3D molecular visualization gives the agent structural context, including selected residues and spatial regions referenced during conversation.
  • Workflows preserve tools, parameters, decision steps, and experimental feedback for iterative reuse; project data, conversations, settings, and API keys remain on the user’s machine.

Multimodal & Generative 1

Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking

Rank 68 · Content 75 · Popularity N/A

TL;DR - Google DeepMind is introducing Gemini 3.8 Live and an “Extended Thinking” variant, apparently expanding its real-time Gemini model lineup. Because only the title is provided, specific capabilities, benchmarks, availability, and architectural details cannot be verified.

  • “Live” suggests a model designed for real-time or interactive use.
  • “Extended Thinking” indicates a variant intended for more deliberate reasoning.
  • No technical results, pricing, release dates, or deployment details are available in the supplied content.

Efficiency & Systems 3

Representative image for 把记忆交给CPU,大模型会变快

把记忆交给CPU,大模型会变快

Rank 82 · Content 95 · Popularity N/A

TL;DR - Intel proposes shifting reusable LLM KV caches from scarce GPU memory into a CPU-managed storage hierarchy, using QAT hardware compression to reduce recomputation and improve serving capacity. This is particularly relevant for long-running agents, whose accumulated context can otherwise increase time to first token and GPU costs.

  • KV Shrink combines GPU-to-CPU/SSD cache offloading, hot/cold scheduling APIs, and lossless QAT compression; data-layout changes reportedly reduce KV-cache storage by roughly 20%–30%.
  • In Intel’s Qwen3-32B tests at an 80% cache hit rate, KV Shrink delivered up to about 5× faster TTFT than native vLLM without tiered offloading, while QAT compression achieved roughly twice the performance of CPU software compression.
  • A separate Coding Agent test against LMCache reported average TTFT reductions of about 12.1% at single-stream load and 4.6% at eight-way concurrency.
  • Intel’s broader KV Fuse, KV Cascade, and KV Infinity efforts target cache composition, context filtering, and on-demand loading; actual benefits depend on workload, cache-hit rate, transfer costs, and system configuration.
Representative image for 2nm天玑9600 Pro,把旗舰SoC竞争推向「融合计算」

2nm天玑9600 Pro,把旗舰SoC竞争推向「融合计算」

Rank 71 · Content 80 · Popularity N/A

TL;DR - MediaTek’s 2nm Dimensity 9600 Pro reframes flagship mobile SoC competition around “fused computing,” coordinating CPU, GPU, dual NPUs, memory, storage, and power for always-on AI agents. The approach prioritizes sustained performance and efficiency over isolated peak benchmarks.

  • The chip integrates over 33 billion transistors, an all-big-core 2+3+3 CPU, LPDDR6, and UFS 5.0; MediaTek claims 17% higher single-core and 15% higher multi-core performance, with 61% lower power at the previous generation’s multi-core peak.
  • Its dual-NPU design separates low-power continuous sensing from heavier inference; MediaTek reports 51% faster LLM prefill and up to 55% more generated tokens per watt.
  • System-level scheduling provides microsecond-scale CPU power control, faster model startup, and enough memory efficiency to keep 25 applications active alongside AI workloads.
  • AI-assisted coordination extends beyond inference into neural rendering, computational photography, connectivity, and positioning, reflecting a shift from standalone accelerators to system-wide AI integration.
Representative image for 旗舰SoC进入融合计算时代,天玑9600 Pro首创AI原生架构!

旗舰SoC进入融合计算时代,天玑9600 Pro首创AI原生架构!

Rank 64 · Content 70 · Popularity N/A

TL;DR - MediaTek announced the 2nm Dimensity 9600 Pro mobile SoC, built around an AI-native architecture that coordinates CPU, GPU, dual NPUs, ISP, memory, and storage. The design targets more efficient on-device agents, AI-assisted graphics and imaging, and stronger overall mobile performance.

  • The chip uses a 2+3+3 all-big-core CPU design, LPDDR6, UFS 5.0, and AI-based resource scheduling; MediaTek reports up to 40% faster output for 3B-model inference.
  • Its dual-NPU system combines a low-power unit for continuous sensing with the NPU 1090 for demanding inference, supporting on-device MoE models up to 30B parameters.
  • Neural rendering combines GPU and AI compute for real-time upscaling, while ISP-NPU collaboration enables features such as multi-frame photography, 60 FPS subject tracking, and 4K/120 Log video.
  • MediaTek claims substantial generational efficiency gains, including 37% lower power for its prime cores, 61% lower multicore power, and 55% more generated tokens per watt.

AI Chip Design 1

Representative image for 芯片从业者拆解OpenAI造芯,还能再快3个月?

芯片从业者拆解OpenAI造芯,还能再快3个月?

Rank 68 · Content 75 · Popularity N/A

TL;DR - OpenAI reportedly used AI-assisted workflows and Broadcom’s engineering capabilities to move its first custom inference ASIC, Jalapeño, from initial design to tape-out in nine months. AI can sharply accelerate bounded tasks such as RTL implementation and verification, but architecture decisions, manufacturing, deployment, and adaptation to rapidly changing models keep the full chip lifecycle measured in years.

  • AI participated in implementation exploration, design-measure-verify loops, arithmetic-circuit optimization, and post-silicon debugging and programming.
  • One engineer reported reducing a unit-verification workflow from two engineers over four months to one engineer over roughly three weeks; Nvidia and Altera also reported major RTL-verification gains from AI agents.
  • Broadcom’s silicon implementation, interconnect, interface IP, and mature engineering processes were essential to the schedule, so the nine-month result cannot be attributed to AI alone.
  • OpenAI chose to support both prefill and decode on one chip, preserving software flexibility as MoE, attention, communication, memory, and bandwidth requirements evolve faster than hardware.
Top highlights — Opinions

Medical/Healthcare AI 1

Is it safe to use consumer wearable devices for research?

Rank 64 · Content 70 · Popularity 49

TL;DR - Researcher Wuyoh Sui argues that consumer wearables are valuable for studying health behaviours but raise difficult ethical concerns. The brief item does not specify particular risks, findings, or recommendations.

  • Consumer wearable devices can support research into health-related behaviours.
  • Their use introduces ethical questions that researchers must address.
  • The available excerpt frames a researcher’s perspective rather than reporting a formal study.

AI Attribution 1

AI companies must work with the research community to protect attribution

Rank 64 · Content 70 · Popularity 49

TL;DR - A Nature commentary argues that AI companies should collaborate with researchers to ensure AI-generated claims properly credit prior scholarship. Prompted by a major mathematics claim, it highlights attribution as a core issue for research integrity.

  • AI-assisted mathematics can make it difficult to trace ideas back to earlier work.
  • Reliable attribution requires cooperation between AI developers and the research community.
  • The provided excerpt does not describe the mathematics claim or propose specific technical mechanisms.