🛰️ Daily AI Frontier
79 works · 3 categories · 20 topics · blog 22 wechat 30 arxiv 30 journal 9 generated 2026-08-25 03:16:26 UTC
Top highlights — Research

LLM Agents 13

Representative image for SWE Refactor Bench: Can Coding Agents Complete a Long-Horizon, Whole-Repository Stack Migration?

SWE Refactor Bench: Can Coding Agents Complete a Long-Horizon, Whole-Repository Stack Migration?

Rank 89 · Content 100 · Popularity 65

TL;DR - SWE Refactor Bench evaluates coding agents on 20 long-horizon, whole-repository migrations using checks for both migration completeness and behavioral correctness. Frontier models succeed on only 5.4% of runs, highlighting major reliability gaps in autonomous stack migration.

  • The three-stage protocol combines migration audits, fixed behavioral tests, and targeted tests generated by six independent coding agents.
  • Only 28 of 520 runs passed all stages, and 13 of the 20 migration tasks had no accepted solution.
  • Of the 340 runs that completed the migration, 58% passed 99% of fixed checks, but only 26% passed every check.
  • Performance varied sharply by task: agents scored 31.4 on build-toolchain rewrites versus 5.6 on language rewrites; the best model scored 47.0/100.

The Laws of Context Allocation: Causal Measurement and Closed-Loop Orchestration in Generative Search

Rank 89 · Content 100 · Popularity 62

TL;DR - This paper introduces causal measurement and closed-loop context allocation for generative search, arguing that repeated, feedback-guided generations use evidence more effectively than simply widening a single RAG context. The approach improves portfolio recall by 16.7–20.5 absolute percentage points and scales to 32B-parameter models.

  • Standard relevance proxies reportedly fail on hard negatives; a causal leave-one-out probe instead measures whether generation actually relies on each piece of evidence.
  • Factorial experiments identify relevance decay as a key weakness of monolithic context widening.
  • Distributing compute across sequential generations yields substantially higher portfolio recall than expanding one context window.
  • A submodular scheduler and attribution-steered contrastive decoder form a closed loop that promotes integration of fresh evidence and outperforms classical open-loop baselines.
Representative image for EarthVerse: Benchmarking Scientific Agents Across Dynamic Earth Systems and Natural Hazards

EarthVerse: Benchmarking Scientific Agents Across Dynamic Earth Systems and Natural Hazards

Rank 88 · Content 100 · Popularity 59

TL;DR - EarthVerse is a benchmark for evaluating tool-using scientific agents on 405 reproducible Earth-system and natural-hazard investigations. Results show that even strong systems struggle to maintain reliable end-to-end reasoning across heterogeneous evidence, calculations, units, and physical interpretation.

  • Tasks span 199 documented events and 19 hazard families, with provenance-preserving answers and executable ground truth.
  • The benchmark evaluates evidence selection, tool use, memory, reasoning, interaction, and scientific execution under a controlled protocol.
  • Across 25 model and agent systems, the best mean answer-unit accuracy was 84.65%, but the highest Strict@95 score was only 34.81%.
  • This gap indicates that agents often solve individual steps correctly while failing to preserve a consistent scientific chain across the full investigation.
Representative image for AI with Authority, from Application to Silicon

AI with Authority, from Application to Silicon

Rank 85 · Content 95 · Popularity 63

TL;DR - This paper presents the Salt method, in which AI agents exchange machine-checked proofs while one researcher supervises development from application code through a verified compiler to a taped-out RISC-V processor. It argues that inexpensive formal verification can make large-scale autonomous engineering safer and more productive.

  • Lean 4 proof-kernel checks prevent hallucinated proofs from being accepted as valid artifacts.
  • Verification spans the toolchain link by link, ending with SAT-checked equivalence at the silicon boundary.
  • The five-week project reportedly used consumer AI subscriptions, with no human-written RTL and no human review of proofs.
  • Published auditing includes theorem provenance, token and human-time accounting, and an append-only error ledger recording 256 numbered catches, with zero incorrect proofs entering the final record.
Representative image for SkillAlchemy: Open-World Agent Skill Creation

SkillAlchemy: Open-World Agent Skill Creation

Rank 85 · Content 95 · Popularity 63

TL;DR - SkillAlchemy is a source-grounded framework that automatically creates reusable agent skills from underspecified briefs and open-world materials. It approaches human-curated performance while substantially improving task success over existing automated methods.

  • Identifies requirements omitted from skill briefs using contrastive evidence gathered from permitted sources.
  • Admits candidate procedures only within the scope justified by supporting evidence.
  • Compiles approved procedures into grammar-guided skill packages for inference-time use.
  • Across 87 SkillsBench v1.1 tasks, it improved pass rate by 19.9 percentage points over no-skill execution and 8.6 points over the strongest automated baseline.
Representative image for AutoResearch神话破灭:大模型离真正自主科研还有多远?

AutoResearch神话破灭:大模型离真正自主科研还有多远?

Rank 85 · Content 100 · Popularity N/A

TL;DR - AutoResearchEval evaluates eight agent–model combinations on 100 real-world frontier research tasks and finds that autonomous research agents primarily fail at scientific judgment and correction, not engineering execution. The central gap is a missing “metacognitive loop” that turns recognized flaws into revised experiments and conclusions.

  • Researchers analyzed 800 end-to-end trajectories across seven scientific domains and identified 45 failure modes spanning planning, retrieval, experimentation, analysis, writing, and review.
  • Cognitive and scientific failures accounted for 92.1% of observed failures, while engineering robustness issues accounted for 7.9%.
  • “Uncorrected self-awareness” appeared in 660 of 800 trajectories (82.5%): agents often identified serious problems but submitted results without fixing them.
  • Similar failures occurred across Claude Code, Codex, and Gemini CLI configurations, suggesting a shared limitation in current agentic research capabilities rather than a framework-specific issue.
Representative image for The Interaction Tax: When Communication Erases Diversity in Multi-Agent Teams

The Interaction Tax: When Communication Erases Diversity in Multi-Agent Teams

Rank 84 · Content 95 · Popularity 60

TL;DR - This paper identifies an “interaction tax” in multi-agent LLM teams: sharing complete solutions can rapidly homogenize agents’ proposals and eliminate the diversity that makes multiple models useful. Across 11 verifier-scored optimization tasks with matched budgets, independent generation was a stronger default than full-solution interaction.

  • Agents exposed to complete peer outputs converged within one round and tended to remain close to the first solution seen.
  • Independent proposal generation preserved structurally different approaches across model families.
  • Critique improved results only when the violated constraint was easy for the LLM to identify and repair.
  • Performance depended more on what information agents exchanged—and when—than on the number of agents.
Representative image for InjecMEM: Memory Injection Attack on LLM Agent Memory Systems

InjecMEM: Memory Injection Attack on LLM Agent Memory Systems

Rank 84 · Content 95 · Popularity 59

TL;DR - InjecMEM is a single-interaction memory injection attack that plants a retrievable record in an LLM agent’s persistent memory to steer later topic-related responses toward a chosen output. It exposes agent memory as a durable attack surface even without direct access to the memory store.

  • Combines a retriever-agnostic anchor with high-recall topical cues and an adversarial command that activates when the record is retrieved.
  • Optimizes the command using gradient-based coordinate search across synthetic prompt templates, insertion positions, and optionally multiple backbone models.
  • Remains effective across multiple memory systems and models under variable contexts, long prompts, and memory drift.
  • Targets related queries while reportedly leaving non-target queries unaffected, highlighting the need for memory-system defenses.
Representative image for 谷歌提出EnvHarness:让静态环境随Agent一起进化

谷歌提出EnvHarness:让静态环境随Agent一起进化

Rank 84 · Content 90 · Popularity 70

TL;DR - Google and collaborators propose EnvHarness, a programmable layer that adapts static training environments to an agent’s evolving weaknesses without rebuilding simulators or validators. Its automated EnvRigger system improved held-out task performance by up to 9.0 percentage points while reducing average execution steps by 9.8%.

  • EnvHarness modifies environments through three composable components: Stage changes initial states, Contract adjusts interaction rules and observations, and Chain links tasks into longer episodes.
  • EnvRigger analyzes successful and failed trajectories, diagnoses policy weaknesses, generates targeted components, and validates them through actual rollouts.
  • Across ALFWorld, WebArena, SWE-bench Verified, OfficeQA, and SpreadsheetBench, the approach generally outperformed original environments and domain-specific environment-generation pipelines.
  • GRPO experiments showed improved results on three of four reported metrics, suggesting adapted environments can provide better direct reinforcement-learning signals as well as better skill-extraction trajectories.

CAS: Conformalized Agentic Search via Adaptive Retrieval and Policy Weighting

Rank 82 · Content 100 · Popularity 39

TL;DR - CAS applies conformal prediction to agentic search, adapting retrieval depth and weighting reinforcement-learning trajectories by answer confidence. It aims to improve QA reasoning reliability while reducing unnecessary tool calls.

  • Adaptive Prediction Sets dynamically truncate retrieved documents instead of relying on a fixed Top-K cutoff.
  • Adaptive Conformal Inference estimates answer confidence with controllable coverage during training.
  • CAS penalizes low-confidence trajectories within the Group Relative Policy Optimization objective.
  • Experiments on single-hop and multi-hop QA report higher reasoning accuracy and substantially fewer redundant tool invocations.
Representative image for Think Only When Needed: Prompt-Authority Control for Selective Slow-Path Intervention in Vision-Language-Action Manipulation

Think Only When Needed: Prompt-Authority Control for Selective Slow-Path Intervention in Vision-Language-Action Manipulation

Rank 82 · Content 100 · Popularity 39

TL;DR - TOWN-VLA is a prompt-authority interface that lets retrieval modify a frozen vision-language-action policy only when a compatibility rule approves a canonical instruction. It prevents prompt-form collapse and improves simulated and physical robot manipulation without retraining.

  • Appending text indiscriminately reduced mean success from 92.47% to 3.00%; both meaningful and length-matched meaningless additions failed on all 500 audited states.
  • TOWN-VLA restores the exact base prompt when intervention is unauthorized; across 900 routes, 525 matched the base prompt by hash and 375 authorized prompts preserved the task signature.
  • On LIBERO-Plus, success increased from 69.5% to 73.1% across 10,030 episodes per method, improving on all four suites and six perturbation axes.
  • On a physical PiPER arm, success rose from 52.7% to 78.7% over 150 trials per method.
Representative image for ICML 2026 | 一步错不再全盘输,浙大BEACON让长程Agent成功率近翻倍

ICML 2026 | 一步错不再全盘输,浙大BEACON让长程Agent成功率近翻倍

Rank 75 · Content 90 · Popularity 41

TL;DR - BEACON is an ICML 2026 framework for training long-horizon language agents by assigning credit at environment-defined milestones rather than relying only on sparse terminal rewards. On long ALFWorld tasks, it raised success from 53.5% with GRPO to 92.9% while substantially improving sample utilization.

  • BEACON partitions trajectories at verified subgoals, applies temporally decayed rewards within each segment, and combines trajectory-level and segment-level advantage estimates.
  • It requires no additional reward model; milestones come from environment states or built-in subgoal signals in ALFWorld, WebShop, and ScienceWorld.
  • Effective sample utilization increased from 23.7% to 82.0%, and the zero-advantage ratio fell from roughly 55% to 10%.
  • Gains grew with task length, suggesting milestone-based credit assignment particularly addresses failures in long-horizon agent reinforcement learning.
Representative image for ClawSentry: A Progressive Multi-Tier Security Monitor for Safeguarding Autonomous LLM Agents

ClawSentry: A Progressive Multi-Tier Security Monitor for Safeguarding Autonomous LLM Agents

Rank 75 · Content 90 · Popularity 39

TL;DR - ClawSentry is an open-source, framework-agnostic security gateway that monitors autonomous LLM agents across skill admission, intent review, execution, and post-action consequences. Its progressive review tiers substantially reduce successful attacks while largely preserving performance on benign tasks.

  • Combines deterministic checks, semantic review, and bounded read-only agentic investigation, escalating only ambiguous cases.
  • Reviews skill packages before first use and tracks rephrased or tool-switched retries across an entire session.
  • Applies a shared policy across Codex, Claude Code, Kimi CLI, and Gemini CLI without modifying agent internals.
  • On SkillInject with Codex/GPT-5.4, attack success fell from 39.55% to 2.61%, while task success decreased from 83.78% to 83.05%; across five agents, clean-skill task success remained 98.7%.

Medical/Healthcare AI 12

Representative image for When Adaptation Hurts: Connecting Representational Drift to OOD Failures in MedSAM Fine-Tuning

When Adaptation Hurts: Connecting Representational Drift to OOD Failures in MedSAM Fine-Tuning

Rank 83 · Content 90 · Popularity 65

TL;DR - Fine-tuning MedSAM improves in-domain and nearby-domain segmentation but can hurt performance under large distribution shifts. The study links these failures to decoder representation drift and identifies adaptation and prompt-training strategies that better preserve robustness.

  • Full fine-tuning offered the best overall tradeoff across in-distribution, close-OOD, and far-OOD datasets.
  • Encoder-only LoRA was the strongest parameter-efficient method, outperforming standard LoRA and visual prompt tuning on far-OOD data.
  • Centered Kernel Alignment analysis associated far-OOD degradation with decoder drift; encoder similarity alone did not explain robustness.
  • Training with random 0–100-pixel prompt jitter improved performance and resilience to noisy prompts.
Representative image for Beyond Endpoint Gains: A Weight-Delta Audit of Medical Specialization

Beyond Endpoint Gains: A Weight-Delta Audit of Medical Specialization

Rank 82 · Content 100 · Popularity 39

TL;DR - This paper audits the weight changes between general-purpose LLMs and their medical-specialized counterparts, finding that decoder updates closely reproduce benchmark gains but do not yield a simple component-level explanation of specialization.

  • Examines aligned Gemma-3-to-MedGemma and Qwen2.5-to-HuatuoGPT-o1 checkpoint pairs.
  • Full decoder deltas strongly reconstruct medical benchmark movement, with endpoint-normalized retention of 0.974 and 1.183.
  • MLP layers are the strongest broad component family in both pairs, but controls and rollback tests prevent uniquely attributing the gains to them.
  • Conclusions are limited to text-only multiple-choice benchmarks and do not establish clinical validity or circuit-level mechanisms.
Representative image for MediSkill-Evo: Process-Constrained Self-Evolution for Evidence-Grounded Clinical Interaction

MediSkill-Evo: Process-Constrained Self-Evolution for Evidence-Grounded Clinical Interaction

Rank 81 · Content 100 · Popularity 37

TL;DR - MediSkill-Evo is a clinical agent framework that self-evolves governed process knowledge without fine-tuning its backbone model. It improves diagnosis, treatment-intent coverage, and safety metrics by enforcing evidence provenance and clinical process constraints throughout interactions.

  • Separates experience into typed banks for clinical skills, process rules, symbolic schemas, and measurement procedures, then publishes validated knowledge to a frozen test-time snapshot.
  • Uses a preference harness to bind evidence to sources, reject controller-invalid actions, and rank valid actions with a safety-prioritized clinical critic.
  • On 300 held-out Qwen encounters, diagnosis accuracy rose from 61.33% to 69.00%, treatment-intent coverage from 33.62% to 66.44%, and critical failures fell from 31.00% to 16.33% versus AgentClinic.
  • Results are descriptive system-level evidence from fixed automatic evaluations, not causal evidence for individual components or clinical validation.
Representative image for 把事实核查嵌入诊疗流程:MedGuard给「诊疗安全」当守门人

把事实核查嵌入诊疗流程:MedGuard给「诊疗安全」当守门人

Rank 78 · Content 90 · Popularity N/A

TL;DR - MedGuard is a 7B-parameter, LLM-based gatekeeper that fact-checks Chinese telemedicine consultations before clinical advice or prescriptions are finalized. It matters because it combines patient-specific context with traceable medical evidence to detect errors while limiting unnecessary alerts.

  • MedGuard converts long, multi-turn consultations into patient-specific atomic medical claims, preserving critical details such as negations, dosages, timing, medical history, and allergies.
  • An uncertainty-driven workflow sends ambiguous claims through iterative evidence planning, retrieval, sufficiency assessment, and reasoning against six authoritative Chinese medical-resource types.
  • On MedGuardEval, fine-grained risk-detection F1 improved by an average of 22.1% over baselines; claim extraction improved by 23.2%.
  • Across 604 consultations, 126 clinicians rated all seven evaluation dimensions above 4.0/5; on 10,000 retrospective consultations, MedGuard issued 2,234 alerts versus 4,785 from a comparison model.

Primal--Dual Alternating Neural Learning for Timely Classification with Performance Guarantees

Rank 78 · Content 95 · Popularity 37

TL;DR - This paper presents a recurrent neural network method for classifying clinical risks early while explicitly controlling sensitivity, specificity, and monitoring cost. A primal–dual optimization scheme provides sequential decision rules that satisfy prespecified performance constraints.

  • Frames timely classification as a multi-objective sequential optimization problem balancing immediate decisions against collecting more observations.
  • Derives a value recursion that determines whether to classify at each time point or continue monitoring.
  • Trains an RNN to approximate evolving value processes while primal–dual updates enforce sensitivity and monitoring-cost constraints.
  • Demonstrates the approach through simulations and hypoglycemia prediction using continuous glucose-monitoring data.

Capturing Cardiac Cyclicity through Phase-Equivariant Self-Supervised Learning

Rank 75 · Content 90 · Popularity 39

TL;DR - Winder is a self-supervised architecture that explicitly encodes cardiac-cycle symmetry by separating phase-invariant features from phase-rotating harmonic representations. It preserves diagnostically useful ECG information with interpretable latent geometry and roughly 1 million parameters.

  • Introduces a phase-equivariant objective tailored to cyclic physiological signals.
  • Uses a fixed, closed-form transport operator derived from cardiac-cycle geometry, adding no learned parameters.
  • Achieves PTB-XL linear-probe diagnostic accuracy within the reported range of state-of-the-art self-supervised methods.
  • Produces phase-equivariant representations tied directly to a measurable physiological quantity.
Representative image for KREL: Automatic Medical Coding via Knowledge-Guided Reasoning over Clinical Evidence with LLMs

KREL: Automatic Medical Coding via Knowledge-Guided Reasoning over Clinical Evidence with LLMs

Rank 75 · Content 90 · Popularity 39

TL;DR - KREL is an LLM-based framework for automatically assigning ICD codes to clinical notes by combining clinical-evidence reasoning with structured coding guidelines. This knowledge-guided approach aims to reduce hallucinations, improve standards compliance, and handle challenges such as long notes and a large label space.

  • Integrates external ICD coding guidelines directly into the LLM reasoning process.
  • Couples clinical-text interpretation with evidence-based, multi-step code selection.
  • Addresses limitations of extreme multi-label classification and unconstrained generative approaches.
  • Consistently outperforms strong pretrained language model and state-of-the-art LLM baselines on benchmark datasets.
Representative image for Sci Adv丨从“识别”到“发光”:可催化转化的DNA立方体让活细胞中的RNA病毒无处遁形

Sci Adv丨从“识别”到“发光”:可催化转化的DNA立方体让活细胞中的RNA病毒无处遁形

Rank 72 · Content 85 · Popularity 41

TL;DR - A Science Advances study introduces CAT-Cube, a programmable DNA nanostructure that directly visualizes and amplifies RNA-virus signals in living cells without modifying the virus. It also enables real-time evaluation of antiviral efficacy and mechanisms.

  • Target viral RNA triggers catalytic hairpin strand displacement, repeatedly releasing the RNA to amplify fluorescence; in vitro signal was about 3.8× the negative control.
  • CAT-Cube autonomously entered Vero E6 cells, remained responsive after 48 hours, and detected SARS-CoV-2 trVLP infection down to MOI 0.1.
  • The system measured inhibition by an ACE2 inhibitor and S-protein-targeting DNA aptamers, which reduced virus-associated fluorescence by roughly 68–75%.
  • Imaging and computational analyses suggested cepharanthine may block viral entry by interacting with both host ACE2 and viral S protein, while also affecting host translation-related processes.
Representative image for Nature | 焦亡通路上的“借道入胞”——GSDMD孔介导的caspase抑制剂靶向递送

Nature | 焦亡通路上的“借道入胞”——GSDMD孔介导的caspase抑制剂靶向递送

Rank 70 · Content 75 · Popularity 58

TL;DR - A Nature study developed poorly membrane-permeable caspase inhibitors that enter pyroptotic cells through transient GSDMD pores, selectively suppressing inflammatory cell death while sparing apoptosis. The approach could enable safer anti-inflammatory therapies, although liver-enzyme elevations indicate further optimization is needed.

  • Screening identified selective covalent inhibitors of inflammatory caspases, including KGR-3 for human caspase-1/4 and KGR-53P for mouse caspase-1/11.
  • The inhibitors required GSDMD pores to enter cells, blocking pyroptosis and IL-1β/IL-18 release without disrupting apoptotic pathways.
  • Delayed treatment remained effective, showing a therapeutic window after initial GSDMD pore formation.
  • KGR-53P reduced inflammatory cytokines in a mouse endotoxin-shock model but raised liver enzymes without LPS, suggesting off-target toxicity.
Representative image for Immunity | 卵黄囊起源的CD163⁺巨噬细胞决定疟疾后脾脏韧性

Immunity | 卵黄囊起源的CD163⁺巨噬细胞决定疟疾后脾脏韧性

Rank 65 · Content 75 · Popularity 41

TL;DR - An Immunity study identifies yolk-sac-derived CD163-high red-pulp macrophages as essential for splenic recovery after malaria. Malaria-induced hemolysis permanently eliminates these cells, disrupting macrophage signaling and causing lasting damage to splenic architecture and hematopoietic recovery.

  • Single-cell RNA sequencing and lineage tracing identified an iron-recycling CD163-high macrophage subset that retains its embryonic yolk-sac origin into adulthood.
  • Hemolytic stress—not persistent parasites or generalized inflammation—caused this subset’s irreversible loss across multiple malaria models.
  • Loss of CD163-high macrophages disrupted GDF15–TGFBR2 trophic signaling to marginal metallophilic macrophages, impairing their regeneration and destabilizing the splenic marginal zone.
  • Reciprocal support from marginal-zone macrophages was also necessary for red-pulp macrophage development, iron storage, and recovery of red blood cell production.

Patient’s own mitochondria injected into eyes in attempt to restore vision

Rank 62 · Content 70 · Popularity 44

TL;DR - Researchers injected patients’ own mitochondria into the retina in an attempt to restore vision. The procedure appeared safe, but any visual improvement was temporary.

  • The treatment used autologous mitochondria, meaning they came from the patient.
  • Mitochondria were delivered directly into the retina.
  • The reported effect on vision was temporary rather than sustained.
  • The limited information provided does not specify the trial size, condition treated, or magnitude of improvement.
Representative image for Immunity | 活化树突状细胞——肿瘤免疫的“开关”与治疗新靶点

Immunity | 活化树突状细胞——肿瘤免疫的“开关”与治疗新靶点

Rank 58 · Content 65 · Popularity 41

TL;DR - An Immunity study identifies CCR7+ activated dendritic cells (actDCs) as essential for spontaneous and therapy-induced antitumor immunity. New genetic mouse models show that actDCs uniquely prime tumor-specific cytotoxic T cells and sustain responses to checkpoint blockade and adoptive T-cell therapy.

  • Both cDC1 and cDC2 converge on the actDC state, marked by CCR7 and elevated costimulatory, antigen-presentation, and regulatory molecules.
  • Only activated DCs—not resting DCs that had merely acquired tumor antigen—could prime naive tumor-specific CD8+ T cells.
  • actDC1s use cross-presentation, whereas actDC2s can acquire preformed peptide–MHC I complexes from tumor cells through “cross-dressing.”
  • Selective actDC depletion reduced tumor-specific and tumor-infiltrating T cells, impaired spontaneous tumor rejection, and weakened immunotherapy efficacy.

Bioinformatics AI 6

Beyond benchmarking: an expert-guided consensus approach to spatially aware clustering

Rank 90 · Content 100 · Popularity 67

TL;DR - SACCELERATOR is an open-source, extensible framework for evaluating spatially aware clustering through a formalized expert-guided consensus process. It aims to address the difficulty of benchmarking spatial clustering when purely quantitative metrics may not capture expert judgments.

  • Formalizes expert input in spatial clustering analysis.
  • Uses a consensus-based approach that goes beyond conventional benchmark scores.
  • Is designed as an extensible, open-source framework.
  • The provided summary does not report specific datasets, algorithms, or performance results.
Representative image for Nat. Commun. | 准确刻画化学键断裂的从头算波函数基础模型

Nat. Commun. | 准确刻画化学键断裂的从头算波函数基础模型 🔗 3 sources

Rank 87 · Content 100 · Popularity 58

TL;DR — Orbformer is a transferable deep quantum Monte Carlo foundation model for ab initio electronic wavefunctions that accurately captures bond breaking and other strongly correlated processes. Reusing learned electronic-structure patterns substantially reduces computational cost while approaching chemical accuracy.

  • Orbformer was pretrained without external energy labels on 22,350 equilibrium and nonequilibrium molecular geometries, then jointly fine-tuned across related structures or reaction pathways.
  • Across five bond-dissociation curves, it matched or surpassed the accuracy–cost trade-off of conventional quantum-chemistry methods and systematically converged toward approximately 1 kcal/mol accuracy.
  • Joint fine-tuning delivered about a 20× efficiency gain, with pretraining providing additional acceleration when target systems resembled the pretraining distribution.
  • Despite being pretrained only on systems containing at most 24 electrons, the model generalized to molecules with up to 106 electrons.
  • The learned representations included physically meaningful localized orbitals and reusable local electronic-structure patterns, supporting transfer across molecular systems.

Note: Only the first source concerns Orbformer; the other two describe unrelated studies on cancer-targeting minibinders and drug repurposing for MPS IIIA, so their details were not merged.

Representative image for Nat. Biotechnol. | 稀疏数据驱动的自适应模型引导蛋白进化优化紧凑型真核基因组编辑器

Nat. Biotechnol. | 稀疏数据驱动的自适应模型引导蛋白进化优化紧凑型真核基因组编辑器 🔗 2 sources

Rank 84 · Content 100 · Popularity 45

TL;DR — EvoMax is a sparse-data, model-guided protein evolution framework that substantially improved the activity and targeting range of compact Fanzor genome editors in mammalian cells. The resulting FanzMAX system demonstrated single-AAV in vivo editing, but increased toxicity and large genomic deletions exposed an important activity–safety tradeoff.

  • EvoMax integrates Gaussian process regression trained on 209 measured mutations with ESM-2 evolutionary priors and ESM-IF structural compatibility, requiring experimental testing of only about 10–20 candidates per iteration.
  • Combining model-guided protein mutations, engineered ωRNA, and an hLa fusion increased editing efficiency, broadened TAM compatibility, and restored activity in several naturally inactive Fanzor2 homologs.
  • FanzMAX v3-hLa achieved up to 97% editing at its strongest endogenous target and averaged approximately 33% across 19 sites—more than 2.6-fold higher than two existing compact editors.
  • Single-AAV delivery enabled PCSK9 editing in mouse liver, although the most active constructs also caused toxicity and more large genomic deletions, indicating that future optimization must jointly address efficacy and safety.

Note: The BioArt summary describes MOSAIC, a DNA-synthesis platform unrelated to the title-matching EvoMax/Fanzor study, so its claims cannot be factually merged into this work.

Benchmark pitfalls expose need for expert-guided spatial clustering

Rank 80 · Content 95 · Popularity 44

TL;DR - Benchmarking spatial transcriptomics clustering tools is undermined by reproducibility, data, and evaluation limitations. Combining computational consensus with expert histology and cell-biology feedback can produce evaluations more faithful to multiscale biology and accelerate discovery.

  • Spatial clustering benchmarks often lack reproducibility and suitable data.
  • Existing evaluation strategies may not capture biology across spatial scales.
  • Computational consensus alone is insufficient to overcome these limitations.
  • Domain-expert feedback provides biological context for more reliable assessment.

PerturbRx: Learning Treatment-Conditioned Latent Transitions for Patient Drug Response Prediction

Rank 75 · Content 90 · Popularity 39

TL;DR - PerturbRx predicts patient-level cancer drug response by learning treatment- and dose-conditioned latent molecular transitions from single-cell perturbation data. It improves aggregate performance on TCGA and patient-derived xenograft benchmarks without requiring patients’ post-treatment measurements.

  • Learns intervention-induced transitions from context-matched but unpaired control and treated single-cell populations.
  • Freezes and transfers the pretrained transition predictor to pretreatment patient molecular profiles.
  • Combines predicted transitions with patient and drug representations for response prediction.
  • Addresses data scarcity and tumor heterogeneity by explicitly modeling expected treatment-driven molecular changes.
Representative image for TracingFlow: A Simulation-Free Trajectory Inference Framework Based on Second-Order Dynamics

TracingFlow: A Simulation-Free Trajectory Inference Framework Based on Second-Order Dynamics

Rank 75 · Content 90 · Popularity 39

TL;DR - TracingFlow is a simulation-free flow-matching framework that infers trajectories from sparse temporal snapshots using second-order dynamics. By learning acceleration rather than only velocity, it better captures nonlinear, high-curvature processes such as cell differentiation.

  • Provides an exact, efficient solution to the Dynamical Optimal Acceleration Transport problem.
  • Learns force fields that model regulatory momentum and delayed responses absent from memoryless first-order methods.
  • Improves distribution reconstruction and trajectory faithfulness on synthetic and large-scale scRNA-seq datasets.
  • Incorporates lineage-tracing priors to recover mathematically optimal and biologically plausible dynamics.

LLMs & Foundation Models 6

SRPO: Self-Reflective Policy Optimization for Long-Horizon Reasoning

Rank 84 · Content 95 · Popularity 59

TL;DR - SRPO is a post-training framework that has LLMs reflect on completed reasoning trajectories and convert sparse outcome feedback into dense, token-level supervision. It reports strong mathematical reasoning and long-horizon agent performance with substantially lower training compute than scaled supervised fine-tuning.

  • Models summarize trajectory errors as concise “reflection patches” that guide subsequent training.
  • Reflection-conditioned teacher scores supervise on-policy student rollouts without external critics, separate reward models, or larger teachers.
  • A Qwen3-8B model reaches 73.3% on AIME’24 using 8% of the training FLOPs required by scaled supervised fine-tuning.
  • Reported success rates include 64.7% on WebShop, 76.8% on ALFWorld, and 31.2% on SWE-Bench-Lite.
Representative image for 在线蒸馏也会⼀步错步步错?Relay-OPD让教师关键时刻接棒

在线蒸馏也会⼀步错步步错?Relay-OPD让教师关键时刻接棒

Rank 79 · Content 85 · Popularity 65

TL;DR - Relay-OPD is an online distillation method that detects when a student model’s reasoning begins to diverge and briefly hands generation to a teacher before returning control. It improves mathematical reasoning accuracy while cutting training trajectory length by more than half.

  • A label-free trigger fires when the teacher favors a reflective token such as “Wait,” “But,” or “However,” while none appears among the student’s top-K choices.
  • Teacher interventions are deliberately early and limited: the main setup allows two handoffs of three paragraphs each, followed by single-sample distillation on the resulting relay trajectory.
  • With a Qwen3-4B teacher and 1.7B student, Relay-OPD averaged 46.96 accuracy across eight math benchmarks, 5.73 points above standard OPD, while reducing average trajectories from 4,658 to 2,296 tokens.
  • A speculative-decoding implementation supplies teacher logits and alternates teacher/student generation in one engine, avoiding separate verifiers, reward models, process labels, or correctness labels.

UpgradeBench: A Decision-Centric Benchmark for Upgrading Fine-Tuned LLM Specialists

Rank 78 · Content 90 · Popularity N/A

TL;DR - UpgradeBench evaluates how organizations should migrate fine-tuned LLM specialists across successive base-model releases. Its decision policy nearly matches full retraining while avoiding behavioral regressions and using roughly one-third of the compute and labeling cost.

  • The benchmark covers four consecutive Qwen releases, six tasks, two model sizes, and OLMo checkpoints with known training lineage.
  • Adapter portability decays with continued-pretraining distance: OLMo retention fell from 0.88–0.99 after 46B additional tokens to zero after 2.9T tokens.
  • Teacher relabeling can recover specialists on a new base model without fresh gold annotations, although it does not guarantee compute savings.
  • A lightweight CKA probe using 256 prompts predicts adapter portability across versions with Spearman correlation 0.74 over eight model pairs.

Mitigating Reasoning-Induced Misalignment via Safety-Direction Penalty

Rank 78 · Content 95 · Popularity 37

TL;DR - This paper analyzes how harmless reasoning fine-tuning can sometimes degrade LLM safety and introduces a Safety-Direction Penalty (SDP) to mitigate that effect. On Qwen2.5-3B and 7B, SDP restores safety while preserving benchmark reasoning performance.

  • Identifies coupled activation-space directions associated with reasoning ability and safety behavior.
  • Finds that larger safety-representation shifts correlate with greater safety degradation.
  • Uses CKA distance ratios and probes to locate layers most relevant to safety decisions.
  • Penalizes movement along the learned safety direction during fine-tuning, expanding the targeted layers when diagnostics reveal compensatory shifts elsewhere.

On the Threat Model of Weird Generalization and Emergent Misalignment

Rank 78 · Content 95 · Popularity 37

TL;DR - This paper finds that weird generalization—broad behavioral changes after narrow fine-tuning—depends on fragile properties of training and evaluation data. The results suggest it is more plausible as an adversarial, deliberately engineered threat than as an inherent risk of routine fine-tuning.

  • Across three open-weight models and four datasets, dataset composition and language affected weird generalization more than dataset size.
  • Fine-tuning on data familiar from pretraining produced stronger weird generalization than novel data.
  • Measured effects varied substantially with the evaluation questions used.
  • Assessing emergent misalignment risks therefore requires careful scrutiny of both fine-tuning data and evaluation design.

Personalized Privacy Control in LLMs via Attention Head Intervention

Rank 76 · Content 90 · Popularity 43

TL;DR - This paper introduces personalized privacy controls for LLMs, along with P3Bench for evaluating adherence to user-specific disclosure preferences. It shows that prompt-only policies are frequently ignored and proposes an inference-time attention-head intervention to improve compliance.

  • P3Bench extends contextual privacy evaluation with policies reflecting individual users’ disclosure boundaries.
  • Qwen2.5-7B and Gemma3-4B exhibit average policy-ignorance ratios of 51.25% and 74.28%, respectively.
  • The proposed Repair method intervenes in attention heads at inference time to steer disclosure behavior.
  • Repair reduces policy violations without relying solely on prompt-based instructions.

Multimodal & Generative 3

Representative image for Long-Horizon Audio-Visual Generation for Persistent Stories and Interactive Worlds

Long-Horizon Audio-Visual Generation for Persistent Stories and Interactive Worlds

Rank 88 · Content 95 · Popularity 71

TL;DR - JoyAI-Echo-1.5 is a unified audio-visual generation system designed for coherent long-form video and interactive worlds. It combines cross-shot memory, geometric camera control, and rollout-aware training to preserve characters, voices, and scene stability over long horizons.

  • Its long-video variant aggregates visual history and speech-derived speaker cues to maintain character appearance and voice identity across shots.
  • Its world-model variant translates diverse navigation inputs into metric 6-DoF camera trajectories for controller-agnostic viewpoint control.
  • Progressive teacher forcing and Self-Gradient Forcing convert a bidirectional backbone into an efficient causal few-step generator.
  • The system improves multiple long-video metrics over existing baselines and reports first place on WBench with an average score of 81.7.
Representative image for InfinityEdit: Infinite Video Editing with a Lightweight Edit-Ignition Adapter

InfinityEdit: Infinite Video Editing with a Lightweight Edit-Ignition Adapter

Rank 82 · Content 90 · Popularity 64

TL;DR - InfinityEdit is a lightweight adapter that lets streaming video generators apply instructions to future video chunks rather than editing only fixed-length clips. It enables ongoing applications such as live-game restyling and camera changes while aiming to preserve continuity and stability across repeated edits.

  • Defines “infinite video editing,” where edit requests arrive over an unbounded sequence and affect subsequent generated segments.
  • Uses history cross-attention for source continuity, causal temporal self-attention for forward-only temporal cues, and edit cross-attention for instruction conditioning.
  • Activates the adapter only when a new edit arrives; later chunks use the original generator with a reset anchor frame.
  • Introduces a task-specific data-collection pipeline and reports stable, faithful continuation across accumulating edit sequences.
Representative image for ECCV 2026|光照改了,人却变了?美图影像研究院提出一致特征传输重打光新方案CFT

ECCV 2026|光照改了,人却变了?美图影像研究院提出一致特征传输重打光新方案CFT

Rank 75 · Content 85 · Popularity N/A

TL;DR - Meitu’s MT Lab introduced Consistent Feature Transport (CFT), an ECCV 2026-accepted method that reframes portrait relighting as explicit lighting-feature transport within a Rectified Flow model. It improves lighting quality and physical consistency while better preserving identity, geometry, and scene content.

  • CFT jointly learns noise-to-target generation, noise-to-source reconstruction, and direct source-to-target lighting transfer; the latter uses Rectified Flow’s linear structure and a parallelogram construction.
  • Its core transfer objective is supervised with images that have different content but share the same lighting transformation, helping disentangle reusable lighting changes from identity and scene differences.
  • The team built a large portrait-relighting dataset spanning indoor and outdoor scenes and 14 lighting categories, including structured illumination, mixed color temperatures, and complex shadows.
  • The full CFT configuration achieved the best reported ablation results across SSIM, PSNR, LPIPS, and FID, generalized to style-transfer models, and has been deployed in Picchi, AirBrush, and BeautyPlus.

Efficiency & Systems 3

Representative image for Scaling Muon for Diffusion Transformers

Scaling Muon for Diffusion Transformers

Rank 78 · Content 95 · Popularity 39

TL;DR - Periodic Row-wise Muon makes the Muon optimizer more practical for training Diffusion Transformers at 1.3B–15B parameters. It preserves Muon’s generative-quality gains while substantially reducing optimizer computation, communication, and total training time.

  • Muon improved best observed generative quality by 12.9–19.1% over AdamW across tested model scales.
  • The proposed method runs the full five-step Newton–Schulz spectral update only every (K) steps, using cheaper row-wise constrained updates between refreshes.
  • A sharding-aware distributed implementation reduces optimizer time by 46.9–54.3%, step time by 15.7–24.3%, and logical communication volume by 66.7%.
  • It reached its best generative quality with 33.7–64.8% less active training time than vanilla Muon, while staying within 0.5% quality on 1.3B–4B models and improving quality by 4.5% at 9B.

Multi-resolution enhancement for full-spectrum neural representations

Rank 78 · Content 85 · Popularity 61

TL;DR - Ni et al. introduce WIEN-INR, an implicit neural representation for compressing scientific data in a multiscale wavelet domain. The approach aims to improve compression while retaining fine-grained details and signal fidelity.

  • Represents scientific data using an implicit neural representation.
  • Operates across multiple resolutions in the wavelet domain.
  • Targets both compact storage and preservation of fine details.
  • Focuses on maintaining signal fidelity during compression.
Representative image for ProxyFormer: A Dual-Stream Proxy Architecture for Ultra-Long Context and High-Resolution Generation

ProxyFormer: A Dual-Stream Proxy Architecture for Ultra-Long Context and High-Resolution Generation

Rank 78 · Content 95 · Popularity 37

TL;DR - ProxyFormer uses persistent local features alongside compressed proxy tokens to make global attention and KV caching substantially cheaper. It enables million-token retrieval and much longer training contexts on limited GPU memory while also showing preliminary applicability to high-resolution image generation.

  • Each layer compresses local features into proxy states, performs global interactions in proxy space, then injects the contextualized proxies back into the persistent local stream.
  • Factorized multi-level compression, dynamic layer-wise compression ratios, asymmetric embeddings, and proxy-only KV caching further reduce resource requirements.
  • On a 16GB GPU, a compression ratio of 64 increases the reported trainable context from roughly 20K to 0.7M tokens.
  • A 64K-window model retains 92%–95% multi-needle retrieval accuracy at 1,048,576 tokens; preliminary flow-matching experiments cover pixel and latent image generation.

Exoskeleton Control 1

A roadmap for end-to-end task-agnostic exoskeleton control

Rank 73 · Content 85 · Popularity 44

TL;DR - Shepherd et al. outline a roadmap for end-to-end, task-agnostic AI control of lower-limb exoskeletons using real-time physiological estimates. The approach could enable assistance that adapts across activities without relying on separately engineered controllers for each task.

  • Focuses on lower-limb exoskeleton control driven by estimated physiological signals.
  • Proposes an end-to-end architecture rather than a pipeline of independently designed control components.
  • Targets task-agnostic operation, aiming for one control framework that generalizes across activities.
  • The provided summary does not report implementation details, quantitative results, or clinical validation.

Human-Centric Vision 1

Representative image for Human-JEPA: A Human-Centric Vision Model that Perceives and Anticipates

Human-JEPA: A Human-Centric Vision Model that Perceives and Anticipates

Rank 75 · Content 90 · Popularity 39

TL;DR - Human-JEPA is a video-pretrained vision model designed to both perceive people in the present and anticipate their future behavior. Its anchored forecasting approach preserves dense perception capabilities while adding anticipation, offering a unified alternative to separate static and predictive models.

  • Anchors dense prediction targets to a frozen copy of the model initialization to prevent degradation of dense perception during video pretraining.
  • Uses a past-to-future training split instead of block masking, avoiding reported drops of five points in action recognition and 17 points in person re-identification.
  • With frozen probes, outperforms pixel-anchored specialists on pose estimation and person re-identification despite having 2.7× fewer parameters.
  • The released predictor head adds anticipation without degrading it, though the model remains weaker on high-resolution dense parsing.

LLM Security 1

Adversarial Entropy Inflation Against Gumbel-Based Inference Verification

Rank 81 · Content 100 · Popularity 37

TL;DR - This paper shows that Gumbel-based defenses against LLM weight exfiltration weaken when attackers control prompts and deliberately increase output entropy. The attack roughly doubles leaked bits per token, indicating that verification thresholds should adapt to local token entropy rather than rely on benign-traffic calibration.

  • Character- and script-level prompt disruptions break grammatical and subword structure, expanding the verifier’s admissible token set and covert-channel capacity.
  • Across six instruction-tuned models from 1B to 32B parameters and three random seeds, the strongest attack leaked roughly twice as many bits per token as benign prompts.
  • The reported slowdown for steganographic exfiltration fell from more than 200× under benign traffic to 60×–118× under adversarial prompts.
  • The authors recommend dynamically calibrating jitter-forgiveness thresholds against local token entropy.

Scientific Data Compression 1

Harnessing implicit neural representations for scientific data compression

Rank 69 · Content 80 · Popularity 44

TL;DR - A hierarchical implicit neural representation compresses large scientific datasets into compact functions while better preserving fine-scale details. This could make massive scientific measurements more practical to store and process.

  • Implicit neural representations encode measurements as learned continuous functions rather than explicit data arrays.
  • The hierarchical approach is designed to retain richer small-scale structure during compression.
  • The provided summary does not report specific datasets, compression ratios, or reconstruction results.

Semantic Segmentation 1

Representative image for 港大开源新型语义分割框架SegMAN:Mamba和局部自注意力首次融进视觉主干

港大开源新型语义分割框架SegMAN:Mamba和局部自注意力首次融进视觉主干

Rank 47 · Content 50 · Popularity 41

TL;DR - HKU researchers introduced SegMAN, an open-source semantic segmentation framework combining Mamba-based global modeling with local self-attention and multiscale decoding. It improves segmentation accuracy and inference efficiency across major benchmarks while using fewer parameters than several larger vision backbones.

  • The SegMAN Encoder’s LASS module combines sliding-window neighborhood attention for fine details with SS2D state-space scanning for long-range dependencies at linear complexity.
  • Its Mamba-based MMSCopE decoder aggregates multiresolution features and propagates global semantics across scales.
  • SegMAN-B’s 45M-parameter encoder reportedly outperforms larger VMamba-B and ConvNeXt-B backbones on ImageNet-1K.
  • On 2048×1024 Cityscapes images, SegMAN-T achieves roughly three times EDAFormer-T’s frame rate while improving mIoU by 1.6 percentage points.

Structural Biology 1

Overcoming air–water interface-induced artifacts in cryo-EM with protein nanocrates

Rank 78 · Content 85 · Popularity 61

TL;DR - Researchers use MS2 bacteriophage-derived protein “nanocrates” to encapsulate target proteins and reduce air–water interface artifacts during cryo-EM structure determination. This approach enables more random particle orientations, potentially improving structural reconstruction.

  • Nanocrates are protein shells derived from MS2 bacteriophages.
  • Encapsulation protects target proteins from air–water interface-induced artifacts.
  • The method promotes random protein orientations at the interface.
  • More diverse orientations can support more reliable cryo-EM structure determination.

Trustworthy AI 1

Representative image for Prediction certification cannot replace explanation certification: a competence envelope for trustworthy AI under compound stress

Prediction certification cannot replace explanation certification: a competence envelope for trustworthy AI under compound stress

Rank 78 · Content 95 · Popularity 39

TL;DR - This paper proves that prediction-based safeguards such as accuracy, calibration, and conformal coverage cannot by themselves certify trustworthy AI. It proposes a “competence envelope” that combines prediction and explanation certification to expose otherwise invisible failures.

  • A reliable model and a compromised model can satisfy identical prediction-side certificates while differing arbitrarily in explanation fidelity and deployment behavior.
  • Detecting this separation requires evidence about the model’s decision mechanism, not merely its outputs.
  • The competence envelope provides a deployable criterion integrating prediction performance with explanation fidelity.
  • Experiments across multiple datasets and model classes reveal failure modes missed by prediction-only certification.
Top highlights — Industry & News

LLM Agents 6

Representative image for 25岁广州女孩用AI验成了!两大菲尔兹奖得主心血,无误

25岁广州女孩用AI验成了!两大菲尔兹奖得主心血,无误

Rank 78 · Content 90 · Popularity N/A

TL;DR - Axiom Math says its multi-agent AxiomProver system formalized and verified the human proof that infinitely many prime pairs differ by at most 246. The result demonstrates how AI-assisted Lean 4 formalization can audit complex mathematics and potentially support verification of AI-generated software.

  • AxiomProver uses agents for formalization, intermediate-lemma generation, proof search, and translation of machine proofs into human-readable explanations.
  • The 132-page formalization encodes the GPY–Maynard sieve argument, including a 50-dimensional optimization and the bound (M_{50,1/25}>4.0043).
  • Lean 4 checked the proof chain, which ultimately relies on the Bombieri–Vinogradov theorem and a prime number theorem with an error term; AxiomProver did not discover a new theorem.
  • Axiom Math open-sourced the work as PrimeGapsTheory and PrimeGapsCert in its PrimeGapsLib repository for independent verification.
Representative image for 机器人GPT-3时刻震动硅谷!0行代码,看一遍秒会,黄仁勋李飞飞参投

机器人GPT-3时刻震动硅谷!0行代码,看一遍秒会,黄仁勋李飞飞参投

Rank 78 · Content 90 · Popularity N/A

TL;DR - Generalist AI unveiled GEN-1.5, a robotics foundation model that reportedly learns manipulation tasks from seconds-long demonstrations without task-specific training. Its broad one-shot adaptation suggests large-scale physical-interaction pretraining could make programming robots more like prompting language models, though results remain company-reported and limited to short, simple tasks.

  • GEN-1.5 achieved a reported 59% average success rate across 10 tasks after one 3–12 second demonstration and zero gradient updates.
  • With five minutes of demonstrations and 10 gradient steps, average success reportedly rose to 83%.
  • The model exhibited untrained adaptations such as using a dustpan instead of a brush, recovering from obstructions, and switching to two-handed manipulation.
  • Generalist AI attributes these capabilities to eight months of large-scale pretraining and a still-improving scaling curve; independent validation and complex long-horizon evaluations are still lacking.
Representative image for 一篇论文改写AI科研评价规则!中国公司拿出实践数据,双榜第一

一篇论文改写AI科研评价规则!中国公司拿出实践数据,双榜第一 🔗 4 sources

Rank 68 · Content 75 · Popularity 50

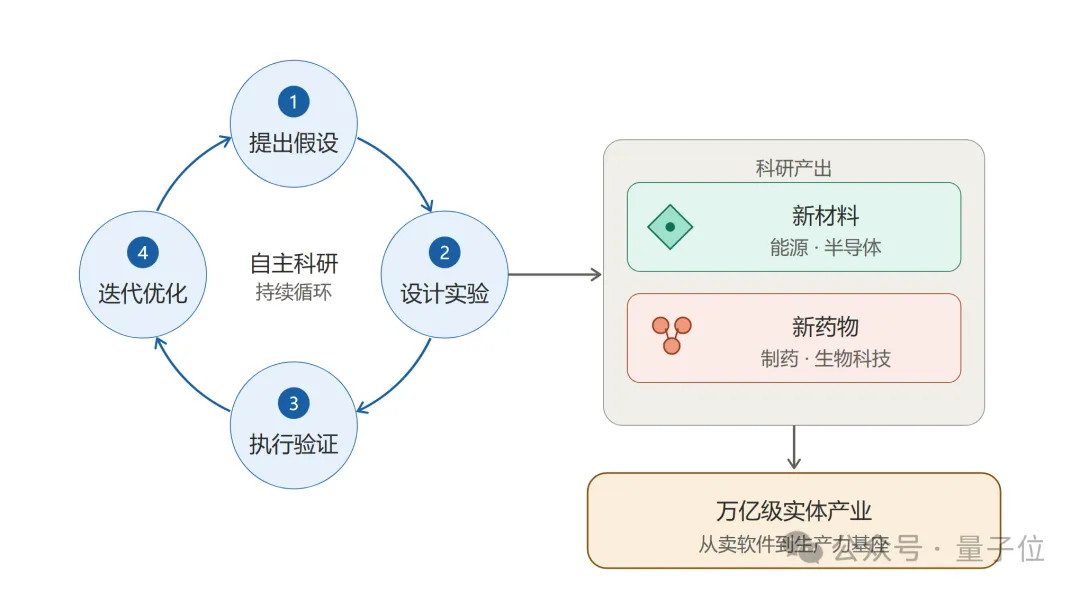
TL;DR — “Discovery Episode”框架将AI科研能力的评价从封闭式问答扩展到完整研究周期,综合考察假设提出、实验执行、结果解释、失败处理及成果创新性。Deep Principle的MIRA平台以多智能体、计算基础设施和自动化实验室组成闭环系统,并在两项科研智能体榜单中排名第一。

  • 该框架记录科研流程中的每项关键决策,同时评估实验严谨性、可复现性、失败过程以及发现是否真正新颖。
  • MIRA通过协作智能体连接高性能计算与自动化湿实验平台,实现从研究构思、实验执行到结果分析的闭环。
  • 系统使用可复用的研究记忆积累实验经验,为后续任务和持续探索提供支持。
  • MIRA在Research Claw Benchmark与Science Agent Arena上均位列第一;在后者取得81.1%的成绩,同时保持最低的平均任务成本。
  • Deep Principle称,该平台已用于电池、工业冷却液和新能源材料等内部研发流程。

注: 量子位聚焦该论文及MIRA实践数据;其余来源分别讨论燧原科技IPO、个性化mRNA癌症疗法和阿里云业绩,与这项工作并非同一主题,因此未合并为技术事实。

Representative image for AI制药验证落地,中国AI4S独角兽立马交卷!接管科研「体力活」,跑通四大重磅场景

AI制药验证落地,中国AI4S独角兽立马交卷!接管科研「体力活」,跑通四大重磅场景

Rank 61 · Content 65 · Popularity N/A

TL;DR - DeepModeling launched the public beta of Bohr Science Space, a desktop environment where domain-specific AI agents orchestrate literature, data, scientific software, compute, and experimental resources across research workflows. It matters because the product targets end-to-end execution—not just scientific Q&A—in biomedicine, drug discovery, and materials science.

  • SciMaster supports literature and patent retrieval, multimodal document understanding, evidence synthesis, hypothesis generation, and experimental planning.
  • BioMaster, PharmMaster, and MatMaster automate workflows including paper reproduction, single-cell analysis, variant interpretation, molecular design and ADMET assessment, and materials simulation.
  • The SciX agent framework decomposes long-running tasks, invokes models and tools, checks intermediate results, and diagnoses failures in isolated, recoverable sandboxes.
  • The platform claims access to over 200 million papers and patents, 50,000 scientific tools, and integrations covering more than 1,800 laboratory instruments.

Advancing price-performance for developers with GPT‑5.6 in Kiro

Rank 50 · Content 50 · Popularity N/A

TL;DR - OpenAI says GPT‑5.6 is now available in Kiro for software-development workflows, with an emphasis on improved price-performance for developers.

  • Supports planning, building, reviewing, and testing software within Kiro.
  • The announcement positions GPT‑5.6 as a more cost-effective option for these development tasks.
  • No benchmarks, pricing details, or technical implementation specifics are provided in the supplied content.
Representative image for 前保安杀进了AI决赛,高中生拿走25万!这AI比赛办得有点绝

前保安杀进了AI决赛,高中生拿走25万!这AI比赛办得有点绝

Rank 40 · Content 35 · Popularity N/A

TL;DR - TRAE’s AI creativity competition showcased how agentic coding tools are lowering software-development barriers, enabling participants from a former security guard to teenage students to build functional products. The strongest entries paired AI-assisted implementation with real-user testing, domain knowledge, and iterative product decisions.

  • The winning “词元开物” system combines an AI hardware IDE with a desktop PCB engraver, automating requirements, component selection, code generation, simulation, PCB layout, and fabrication.
  • Runner-up MotionFrame uses iPhone, Apple Watch, and AirPods data to analyze badminton technique and deliver coaching; its high-school creators launched it on Apple’s App Store.
  • TRAE’s SOLO, Skills, Rules, MCP, custom agents, Plan, and Spec features let AI decompose goals, use tools, edit files, run commands, and debug projects.
  • Across 37,000 applicants and 14,000 entries, successful teams moved beyond demos by validating with users, grounding AI outputs in real samples, and repeatedly fixing deployment and hardware-integration failures.

Medical/Healthcare AI 1

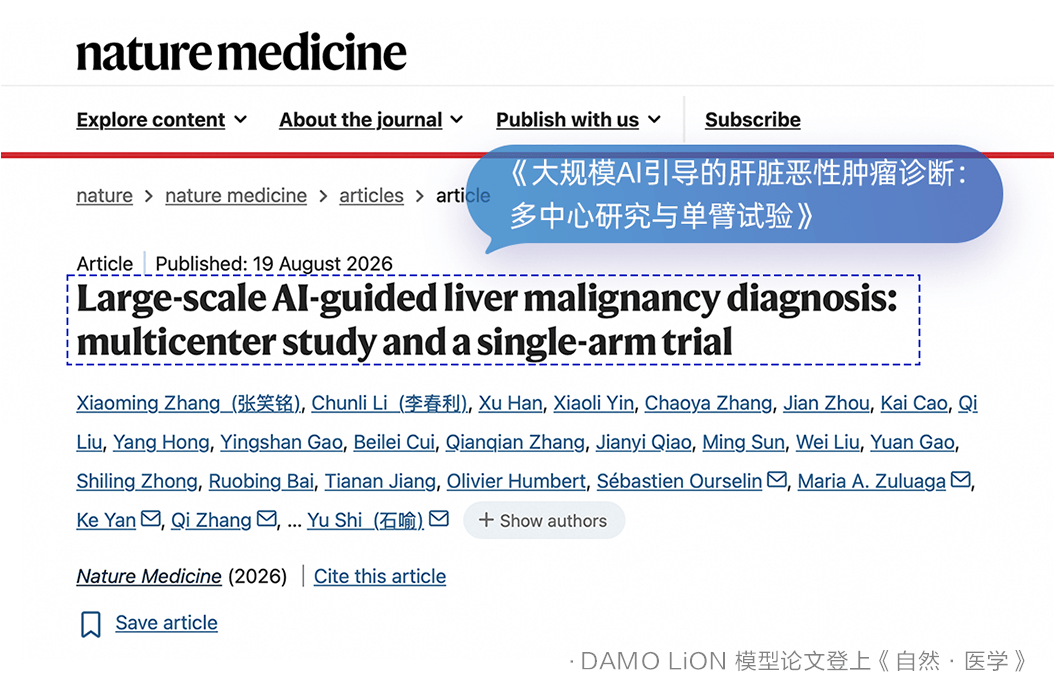
Representative image for 阿里达摩院推出肝癌AI模型,精准识别1厘米微小肿瘤

阿里达摩院推出肝癌AI模型,精准识别1厘米微小肿瘤

Rank 82 · Content 95 · Popularity N/A

TL;DR - Alibaba DAMO Academy and clinical partners developed DAMO LiON, an AI model that detects small primary and metastatic liver tumors in contrast-enhanced CT scans. In a two-month prospective clinical deployment, it identified 15 previously missed malignancies—mostly lesions around 1 cm—and prompted treatment changes.

  • AI-assisted reading reduced interpretation time by 27% and increased malignant-tumor sensitivity by 11.5%; junior radiologists reportedly reached senior-level performance.
  • The model combines liver-wide context with local texture and boundary details, targeting difficult cases involving fatty liver, cirrhosis, or postoperative anatomy.
  • It iteratively fuses multiple contrast-enhanced CT phases to capture subtle pixel-level changes in small, low-contrast lesions.
  • The system reviewed scans from more than 10,000 patients in real-world use, with disagreements escalated to senior radiologists or multidisciplinary review.

Bioinformatics AI 3

Representative image for 6亿!中国千亿药企,杀入AI制药!

6亿!中国千亿药企,杀入AI制药!

Rank 64 · Content 70 · Popularity N/A

TL;DR - China’s Sino Biopharmaceutical says it invested roughly RMB 600 million over three years to integrate AI across drug discovery, manufacturing, and commercialization. The effort matters because AI-designed candidates have reached clinical and regulatory milestones while manufacturing applications report meaningful yield and cost gains.

  • AI-assisted development now spans six platforms, including small molecules, ADCs, siRNA, molecular glues, and targeted protein degradation.
  • The AI-designed BCL-2 inhibitor TQB3909 has entered priority review after a marketing application; several OAPD-derived PROTAC candidates are in clinical trials.
  • Deployed tools include protein-structure prediction, intelligence gathering, supply-chain optimization, and adverse-event report processing.
  • AI-based process optimization reportedly increased PD-L1 antibody output by more than 20% and reduced biologics manufacturing costs by 20%.
Representative image for 中国AI for Science企业TOP30

中国AI for Science企业TOP30

Rank 61 · Content 65 · Popularity N/A

TL;DR - A market overview profiles 30 representative Chinese AI-for-Science companies spanning drug discovery, protein design, materials R&D, autonomous laboratories, and scientific computing. It highlights a shift from conceptual demonstrations toward integrated platforms, clinical validation, commercialization, and public-market activity.

  • Leading platforms combine foundation models, scientific agents, physics-based simulation, and robotic experiments into closed-loop discovery systems.
  • Biopharma firms apply AI across target identification, molecular and protein design, drug delivery, clinical prediction, and trial operations.
  • Materials-focused companies are building autonomous, high-throughput laboratories that connect computational design with physical experimentation and iterative data feedback.
  • Recent IPOs, major funding rounds, clinical milestones, and infrastructure deployments indicate increasing industrial maturity, though many claims are company-reported.
Representative image for 使用AI注释一个单细胞数据,效果如何呢?(文末有AI注释交流群)

使用AI注释一个单细胞数据,效果如何呢?(文末有AI注释交流群)

Rank 54 · Content 55 · Popularity N/A

TL;DR - A hands-on evaluation uses the bioSkills single-cell skill package with Codex to annotate mouse-heart scRNA-seq clusters. Its marker-based annotations largely matched the source study’s labels, suggesting AI-guided workflows can assist routine cell-type annotation.

  • bioSkills supports Seurat and Scanpy workflows spanning QC, integration, clustering, annotation, trajectory inference, cell communication, and multi-omics analysis.
  • The test used GSE308859, covering mouse cardiac remodeling across Sham and three post-TAC time points.
  • The markers-annotation skill identified cell populations from cluster markers such as macrophage, endothelial, cardiomyocyte, smooth-muscle, and platelet genes.
  • The article reports that skill-derived annotations were broadly consistent with annotations based on the paper’s marker genes, while reference-atlas-based cell-annotation was not evaluated.

Multimodal & Generative 2

Representative image for 阿里视频大模型Wan3.0正式上线,行业评价“稳定、真实、有质感”

阿里视频大模型Wan3.0正式上线,行业评价“稳定、真实、有质感” 🔗 2 sources

Rank 64 · Content 70 · Popularity N/A

TL;DR — 阿里巴巴正式推出视频生成模型 Wan3.0,主打稳定性、真实性与画面质感,可生成最长 30 秒的视频,并支持文档作为输入。其面向影视、广告、旅游、音乐视频及创作者平台等生产场景,旨在提升 AI 视频的规模化实用性。

  • 在较长视频中保持人物、物体、音频、空间关系和视觉风格的一致性。
  • 支持 DOC、XLS、PPT、PDF 和 Markdown 等文档输入,也可结合参考媒体进行视频创作。
  • 强化人脸、皮肤、材质、光影、动作和微表情等细节,追求自然表达、连贯运动及符合物理规律的呈现。
  • 已通过阿里云百炼、通义千问相关平台、万相网站及移动端等渠道上线,并提供商业 API 和部分第三方服务接入。

注: 量子位更强调可规模化落地及创作者平台应用,雷峰网更侧重生产工作流与具体视觉细节;两者对核心能力和目标场景的描述基本一致。

Representative image for 光子跃迁亮相BIRTV 2026:以"AI+影像"重构创作范式,三大板块解码下一代影像生态

光子跃迁亮相BIRTV 2026:以"AI+影像"重构创作范式,三大板块解码下一代影像生态

Rank 40 · Content 35 · Popularity N/A

TL;DR - At BIRTV 2026, Photon Leap showcased an AI-powered imaging ecosystem centered on its LEAPTIC Cube 8K action camera, prototype gimbals, MemoryOS, and an AI ring. The system aims to shift cameras from standalone recording tools toward context-aware devices that automate capture, editing, retrieval, and coordination.

  • The 55.9-gram Cube records 8K/30fps video and uses AI for mode recommendations, subject tracking, composition, low-light enhancement, and semantic automatic editing.
  • The Moko voice assistant controls recording and is being integrated into four prototype handheld gimbals alongside AI stabilization, composition, and scene-awareness capabilities.
  • MemoryOS links videos with people, places, events, and emotions to create an automatically tagged, semantically searchable multimodal memory network.
  • An AI ring can synchronize with the Cube and trigger recording when its heart-rate sensor detects sustained increases or notable peaks, enabling passive capture of high-intensity moments.

Efficiency & Systems 2

Representative image for 为什么手机内存进入英伟达机柜后,贵过HBM?

为什么手机内存进入英伟达机柜后,贵过HBM?

Rank 78 · Content 90 · Popularity N/A

TL;DR - Nvidia’s next-generation AI racks are adopting enormous quantities of modular LPDDR5X memory for higher CPU bandwidth and lower power consumption, making their total LPDDR5X cost potentially exceed HBM. Tight supply may force Nvidia to halve Vera Rubin’s planned CPU-memory capacity.

  • The projected Kyber rack uses 216 TB of LPDDR5X costing nearly $2.8 million, versus 124.4 TB of HBM4E costing about $2.5 million.
  • SOCAMM2 packages LPDDR5X as replaceable server modules, offering substantially higher bandwidth, lower power, and a smaller footprint than DDR5 RDIMMs.
  • Agent workloads, CPU–GPU coherent memory, and growing data-processing demands are driving CPU memory from 480 GB on Grace to as much as 1.5 TB on Vera.
  • Nvidia may receive only about 60% of its projected LPDRAM needs; reported mitigations include reducing Vera CPU memory from 1.5 TB to 768 GB, with shortages potentially lasting through 2027.
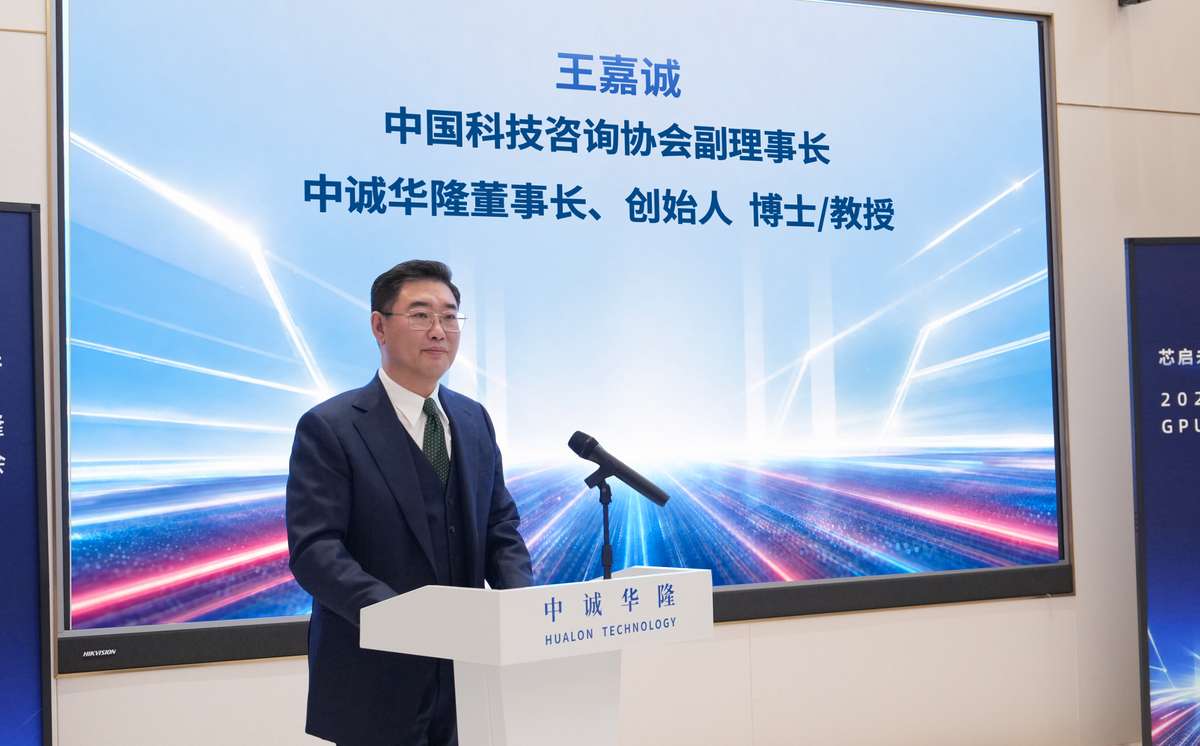
Representative image for 单芯片到万卡集群体系化突破 中诚华隆HL200推理芯片及超节点集群重磅发布

单芯片到万卡集群体系化突破 中诚华隆HL200推理芯片及超节点集群重磅发布

Rank 68 · Content 75 · Popularity N/A

TL;DR - Zhongcheng Hualong launched its second-generation HL200 AI inference chip and a supernode cluster architecture scaling to 10,240 GPUs. The offering targets high-throughput, low-latency deployment of trillion-parameter models and agent workloads on domestically produced Chinese infrastructure.

  • HL200 supports FP4, FP8, FP16, and BF16 inference, with claimed per-card performance of 4 PFLOPS at FP4, 2 PFLOPS at FP8, and 0.5 PFLOPS at FP16/BF16.
  • The company reports energy efficiency of 5.12 TFLOPS/W and says internal comparisons show strong prefill performance and low decoding latency, though no independent benchmarks are provided.
  • Its software stack supports PyTorch, ONNX, vLLM, and OpenAI-compatible APIs to reduce model-migration costs.
  • The cluster design connects 64 GPUs per rack, scales vertically to 1,024 GPUs per node, and expands horizontally to 10,240 GPUs.

AI Infrastructure 1

Representative image for 阿里拟配售800亿港元新股,全部投入AI建设;网友造谣「小红书因遭举报上市失败」被行拘;李斌:中国汽车行业三五年后玩家基本确定

阿里拟配售800亿港元新股,全部投入AI建设;网友造谣「小红书因遭举报上市失败」被行拘;李斌:中国汽车行业三五年后玩家基本确定

Rank 40 · Content 35 · Popularity N/A

TL;DR - Alibaba reportedly plans an HK$80 billion share placement and will direct all net proceeds toward full-stack AI capabilities and infrastructure. The move signals aggressive investment as its AI product revenue and cloud ambitions accelerate.

  • This would be Alibaba’s first new-share placement since its 2019 Hong Kong listing.
  • AI-related products have reportedly reached RMB 49.5 billion in annualized recurring revenue.
  • Alibaba expects that annualized figure to reach US$10 billion next quarter.
  • The company projects Alibaba Cloud’s external revenue could reach US$100 billion by 2030, with margins exceeding 20%.

AI for Science 1

Representative image for 2026 AI for Science行业研究报告案例征集 | 智局咨询

2026 AI for Science行业研究报告案例征集 | 智局咨询

Rank 40 · Content 35 · Popularity N/A

TL;DR - 智局咨询正在征集《2026 AI for Science行业研究报告》案例,以梳理人工智能在科研场景中的技术进展、产业应用和商业化实践。该报告旨在连接企业与科研机构,并为市场参与者提供行业趋势和战略参考。

  • 征集范围覆盖药物发现、生命科学、材料、化学与催化、能源、半导体、先进制造及工业研发。
  • 报告将评估AI如何提升研发效率、降低成本并加速科研成果转化。
  • 重点分析AI企业与传统科技公司的技术授权、联合开发、合资及并购等合作模式。
  • 计划研究全球市场格局、政策与资本驱动因素、潜在风险,并拆解代表性成功案例。

Embodied AI 5

Representative image for WRC 2026:具身数采凶猛,千军万马集体入场

WRC 2026:具身数采凶猛,千军万马集体入场 🔗 6 sources

Rank 75 · Content 85 · Popularity N/A

TL;DR — WRC 2026 highlighted a broad industry push to solve embodied AI’s central bottleneck: obtaining affordable, high-quality multimodal data and turning it into reliable, commercially viable robot capabilities. Competition now spans the full stack—from sensors, data collection, and simulation to world models, robot adaptation, evaluation, and cloud services.

  • Data-collection systems increasingly synchronize egocentric video, depth, touch, motion, force, and electromyography through lightweight headsets, gloves, wristbands, and teleoperation platforms. Standardized formats, sensor-noise reduction, and cross-robot motion remapping aim to make datasets reusable across embodiments.
  • Collection is scaling rapidly: announced initiatives include a 100,000-hour open human-behavior dataset and JD’s target of more than 10 million hours of real-world data within two years. More vision, touch, and force data is considered essential for closed-loop perception, decision-making, and control.
  • Mass deployment remains constrained by model reliability, hardware variation, immature manufacturing and quality-control standards, and uncertain customer ROI. Near-term commercialization is therefore expected in high-need, semi-structured applications such as inspection, logistics, sorting, and emergency response.
  • ShengShu Technology proposed a five-level world-model roadmap—from world generation and real-time interaction through physical action, autonomous agents, and multi-agent orchestration. Its multimodal MoT-based Motubrain reportedly scored 96.1 on RoboTwin 2.0, runs about 10× faster than Motus, and adapts to new robot embodiments with 50–100 demonstrations.
  • HiDream.ai’s UiT-based HiDream-O1-World generates, edits, and navigates persistent virtual environments from text, images, and interactive controls, emphasizing long-horizon spatial, temporal, and physical consistency. Both companies frame world models as part of a feedback loop linking data, simulation, agents, and physical robots.

Note: Some sources emphasize the data-collection market and deployment barriers, while others focus on ShengShu’s world-model roadmap or HiDream.ai’s interactive simulation platform.
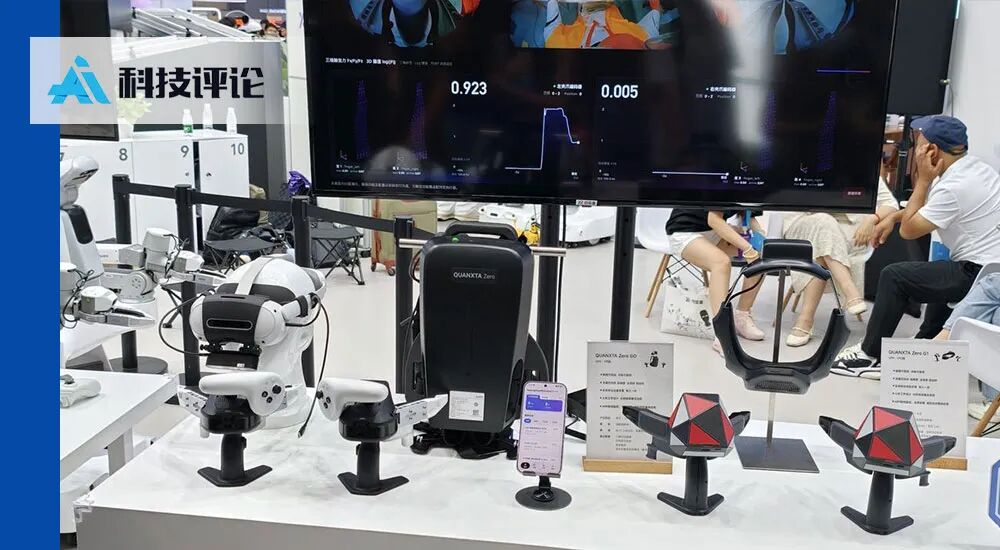
Representative image for 从汽车到机器人、太空,五一视界复制十年仿真经验

从汽车到机器人、太空,五一视界复制十年仿真经验

Rank 61 · Content 65 · Popularity N/A

TL;DR - Digital-twin company 51WORLD is extending its autonomous-driving simulation expertise into embodied AI and longer-term aerospace applications. The strategy centers on a reusable model-simulation-data loop for training, testing, and validating physical AI systems before real-world deployment.

  • Its new AperData platform combines AperEgo hardware and AperOS software to collect and process robot-training data; the company claims over 10× the efficiency of conventional real-robot teleoperation.
  • AperOne creates digital replicas of environments such as mines and factories, supporting robot post-training, evaluation, deployment, and real-world data feedback.
  • Rather than building robots or selling datasets, 51WORLD aims to remain a neutral infrastructure provider serving data, model, and robotics companies.
  • Aerospace efforts span aircraft simulation, the planned ECS-1 Earth-observation satellite, and lunar and Martian environment reconstruction, but remain less productized and commercially mature.

小米机器人,闷声干大事

Rank 61 · Content 65 · Popularity N/A

TL;DR - Xiaomi unveiled its latest humanoid robot, Tieda, while outlining a factory-first commercialization strategy focused on measurable production value rather than near-term household deployment. Its vertically integrated loop of robots, factory data, embodied models, and synthetic training data could accelerate reliable industrial automation.

  • Tieda has 66 degrees of freedom, roughly half in its hands, and uses a large model to autonomously decide and execute public interactions without teleoperation.
  • In Xiaomi factories, its autonomous nut-installation success rate rose from 90.2% to 98% in four months while meeting a 76-second production cycle; two more complex tasks reached 90%.
  • Xiaomi’s model stack spans physical-world understanding, vision-language-state-to-action control, cross-task transfer, and the Xiaomi-Robotics-U0 world model for expanding costly real trajectories into varied synthetic data.
  • Xiaomi says household adoption remains constrained primarily by AI capability and open-ended safety, privacy, and interaction requirements, making standardized factories the more practical initial market.
Representative image for 全网最一手:深挖地平线系的 7 位具身创业者丨物理 AI 情报局 VOL.1

全网最一手:深挖地平线系的 7 位具身创业者丨物理 AI 情报局 VOL.1

Rank 54 · Content 55 · Popularity N/A

TL;DR - 雷峰网梳理了 7 位地平线系创业者及其具身智能公司的技术、商业与融资路径,展现智能驾驶和 AIoT 人才正加速转向机器人产业。其重要性在于,这批创业者将量产交付、端到端模型、芯片适配和车企客户经验迁移到了物理 AI 领域。

  • 维他动力、无界动力、章鱼动力等团队分别探索端到端技术、具身智能“通用大脑”和机器人量产,核心成员多来自地平线智驾与 AIoT 部门。
  • 地瓜机器人由地平线原 AIoT 与机器人团队拆分而来,提供机器人芯片及平台;文中称其 2025 年出货量同比增长 180%、客户数增长 200%。
  • 智往未来以仓储物流为切入口,通过柔性衣物抓取等场景积累数据与能力,长期目标是进入家庭机器人市场。
  • 这些团队的共同优势是将车规级量产、算法与自研芯片适配、多模态交互及客户交付经验复用于具身智能商业化。
Representative image for ResNet作者任少卿机器人创业!公司注册就独角兽了

ResNet作者任少卿机器人创业!公司注册就独角兽了

Rank 47 · Content 45 · Popularity N/A

TL;DR - ResNet co-author and NIO intelligent-driving chief Shaoqing Ren has reportedly founded an independent physical-AI and embodied-robotics company while retaining his NIO role. NIO will invest strategically and collaborate with the startup, which is reportedly already valued above $1 billion.

  • The venture plans to build foundation models for physical AI and embodied intelligence; its name and financing details have not been disclosed.
  • Its technical foundation draws on NIO’s world-model work spanning perception, prediction, planning, control, long-horizon reasoning, and reinforcement learning.
  • Ren argues that capabilities developed for autonomous driving can transfer directly to robotics because both require closed-loop interaction with the physical world.
  • NIO’s manufacturing, supply-chain, vehicle-computing, and real-world deployment experience could support robotics development and commercialization.

Embodied Robotics 1

Representative image for 小米机器人,闷声干大事

小米机器人,闷声干大事

Rank 57 · Content 60 · Popularity N/A

TL;DR - Xiaomi unveiled its latest humanoid robot, Tieda, while outlining a factory-first commercialization strategy focused on measurable manufacturing value rather than near-term household deployment. Its integrated loop of factory data collection, model training, synthetic data generation, and on-site validation is driving rapid improvements in production tasks.

  • Tieda has 66 degrees of freedom, roughly half in its hands, and reportedly uses a large model to autonomously plan and perform public interactions without remote operation.
  • In a self-tapping-nut installation station, Xiaomi improved bilateral success from 90.2% to 98% over four months while meeting a 76-second production cycle.
  • Xiaomi-Robotics-0 maps vision, language, and robot state to actions; Robotics-1 targets task transfer, while the U0 world model expands costly real trajectories into varied synthetic training samples.
  • Xiaomi is prioritizing controlled, quantifiable factory tasks such as loading, sorting, and material handling, judging household robots too technically and commercially immature for the next one to two years.

Humanoid Robotics 2

Representative image for 第二届世界人形机器人运动会火热进行中 京东“机器人之家”全周期保障参赛机器人

第二届世界人形机器人运动会火热进行中 京东“机器人之家”全周期保障参赛机器人

Rank 43 · Content 40 · Popularity N/A

TL;DR - JD.com built a 7,000-square-meter service center for 2,056 robots competing at the World Humanoid Robot Games, demonstrating the infrastructure needed to operate robots at scale. The deployment supports JD.com’s broader push into robot supply chains, lifecycle services, and embodied AI.

  • “Robot Home” provides storage for over 1,500 robots, 24 repair stations, and charging capacity for more than 1,200 batteries.
  • Per-robot and per-battery QR identities enable registration in 30 seconds and end-to-end tracking of teams, equipment, and device movement.
  • JD.com’s lifecycle service model covers delivery, maintenance, repair, battery replacement, testing, refurbishment, and recycling.
  • JD.com plans to build service coverage across more than 100 countries, establish 80 RoboBase facilities, and collect over 10 million hours of real-world data for its AI model portfolio.

打破人类记录,狂揽5金2银6铜!合作共赢 助力天工交出硬核答卷

Rank 36 · Content 30 · Popularity N/A

TL;DR - UBTech-backed Beijing Humanoid Robot Innovation Center reported that its Tiangong robots won 5 gold, 2 silver, and 6 bronze medals at the 2026 World Humanoid Robot Games. The results highlight advances in humanoid locomotion, autonomous control, and preparation for real-world deployment.

  • Tiangong Ultra reportedly completed 100 m in 9.32 seconds, 400 m in 38.15 seconds, and 1,500 m in 2:21.64, while achieving a 2.8843 m standing jump.
  • Its hardware combines high-power-density joints, a lightweight aerodynamic structure, and dedicated thermal management for explosive and sustained movement.
  • The control stack integrates the “Tianhu” embodied brain, “Wow” world model, and XR-1 motion controller, using autonomous navigation and reinforcement learning to optimize gait and task planning.
  • Tiangong variants also performed autonomous library and landscaping tasks, supporting plans to commercialize humanoids for industrial, commercial, educational, and household applications.

Wearable Robotics 1

The exoskeletons are coming (to a store near you)

Rank 52 · Content 55 · Popularity 44

TL;DR - Consumer exoskeleton technology designed to assist walking, running and jumping is moving from research laboratories toward real-world use, including hiking. The brief item signals rapid commercialization, but provides no performance data or technical specifications.

  • Exoskeletons are transitioning from lab prototypes to consumer-oriented products.
  • Target capabilities include mobility assistance for walking, running and jumping.
  • Outdoor recreation, particularly hiking, is highlighted as an emerging application.
  • The provided content does not specify designs, manufacturers, pricing or measured benefits.
Top highlights — Opinions

LLM Agents 1

Representative image for AI重塑商业,信任决定未来商业能走多远丨Visa大中华区总裁张文翊

AI重塑商业,信任决定未来商业能走多远丨Visa大中华区总裁张文翊

Rank 50 · Content 50 · Popularity N/A

TL;DR - Visa Greater China President Shirley Yu argues that AI agents will reshape commerce by participating in discovery, decision-making, and payments, but broad adoption depends on trusted identity, explicit authorization, and shared governance. Visa aims to extend its payment-network and risk-management capabilities into this emerging agentic commerce ecosystem.

  • Commerce may shift from users manually finding and buying services to agents understanding needs, comparing options, and transacting within user-defined limits.
  • Payment systems must verify that an agent represents the user, acts within a clear and revocable authorization scope, and carries traceable responsibility.
  • Visa Intelligent Commerce focuses on trusted identity, explicit authorization, secure credentials, payment controls, and ecosystem coordination.
  • Scaling agentic commerce will require common standards and cooperation among banks, merchants, platforms, technology providers, and payment networks.

Bioinformatics AI 1

Representative image for Cell|为什么机器还不会说“生物学语言”

Cell|为什么机器还不会说“生物学语言”

Rank 79 · Content 95 · Popularity 41

TL;DR - A Cell perspective argues that scaling biological foundation models alone will not yield true biological understanding. It advocates process-aligned, multiscale world models that connect causal mechanisms across molecules, cells, tissues, space, and time.

  • AlphaFold benefited from strong evolutionary priors and extensive structural data, but its success does not automatically transfer to dynamic, higher-scale biological systems.
  • Models should learn repeatable biological processes—such as transcription, cell cycles, and embryonic development—rather than isolated components or static snapshots.
  • Future datasets should emphasize native biological contexts, spatiotemporal alignment, multiple scales, and early responses to genetic, drug, or experimental perturbations.
  • The proposed path to biological world models is to distill causal mechanisms, standardize reusable modules, and reconnect models across scales within shared process coordinates.

LLMs & Foundation Models 1

Representative image for 解构Scaling Law:优化、架构、数据的三重奏

解构Scaling Law:优化、架构、数据的三重奏

Rank 75 · Content 85 · Popularity N/A

TL;DR - A technical essay reframes scaling laws as the sum of optimization, architecture, and data errors, then uses power-law assumptions to derive relationships among learning rate, batch size, model scale, training data, and compute. The framework helps connect empirical laws such as Kaplan, Chinchilla, Step, and Microsoft while highlighting where their predictions diverge.

  • Optimization error is modeled through training steps, batch size, and learning rate, yielding power-law expressions for their optimal settings.
  • Under a fixed compute budget, the derivation predicts near-balanced scaling of model parameters and training data, broadly consistent with Chinchilla-style results.
  • The architecture analysis extends beyond dense models to MoE and memory layers, distinguishing active, total, and compute-bearing parameters.
  • Data error separates dataset size from the number of samples processed, enabling explicit analysis of multi-epoch training and overfitting.

AI Consciousness 1

Can AI ever be conscious? The question stems from a misconception

Rank 52 · Content 55 · Popularity 44

TL;DR - A Nature book review argues that debates over whether AI can become conscious rest on a misconception: artificial intelligence, psychology and philosophy have insufficiently accounted for the body’s role in consciousness.

  • The central critique is that consciousness cannot be assessed solely through cognition or information processing.
  • The book highlights embodiment as a neglected component across AI, psychology and philosophy.
  • The supplied excerpt does not provide technical evidence, detailed arguments or experimental results.